# Introduction
URL: /docs
***
title: Introduction
description: Learn how to get started with Logspot.
icon: BookOpenIcon
------------------
Logspot is analytics for go-to-market teams. It measures product and website activity, connects each event to the person and company behind it, enriches those accounts, surfaces the signals worth acting on, and runs the actions that follow, all from one first-party snippet.
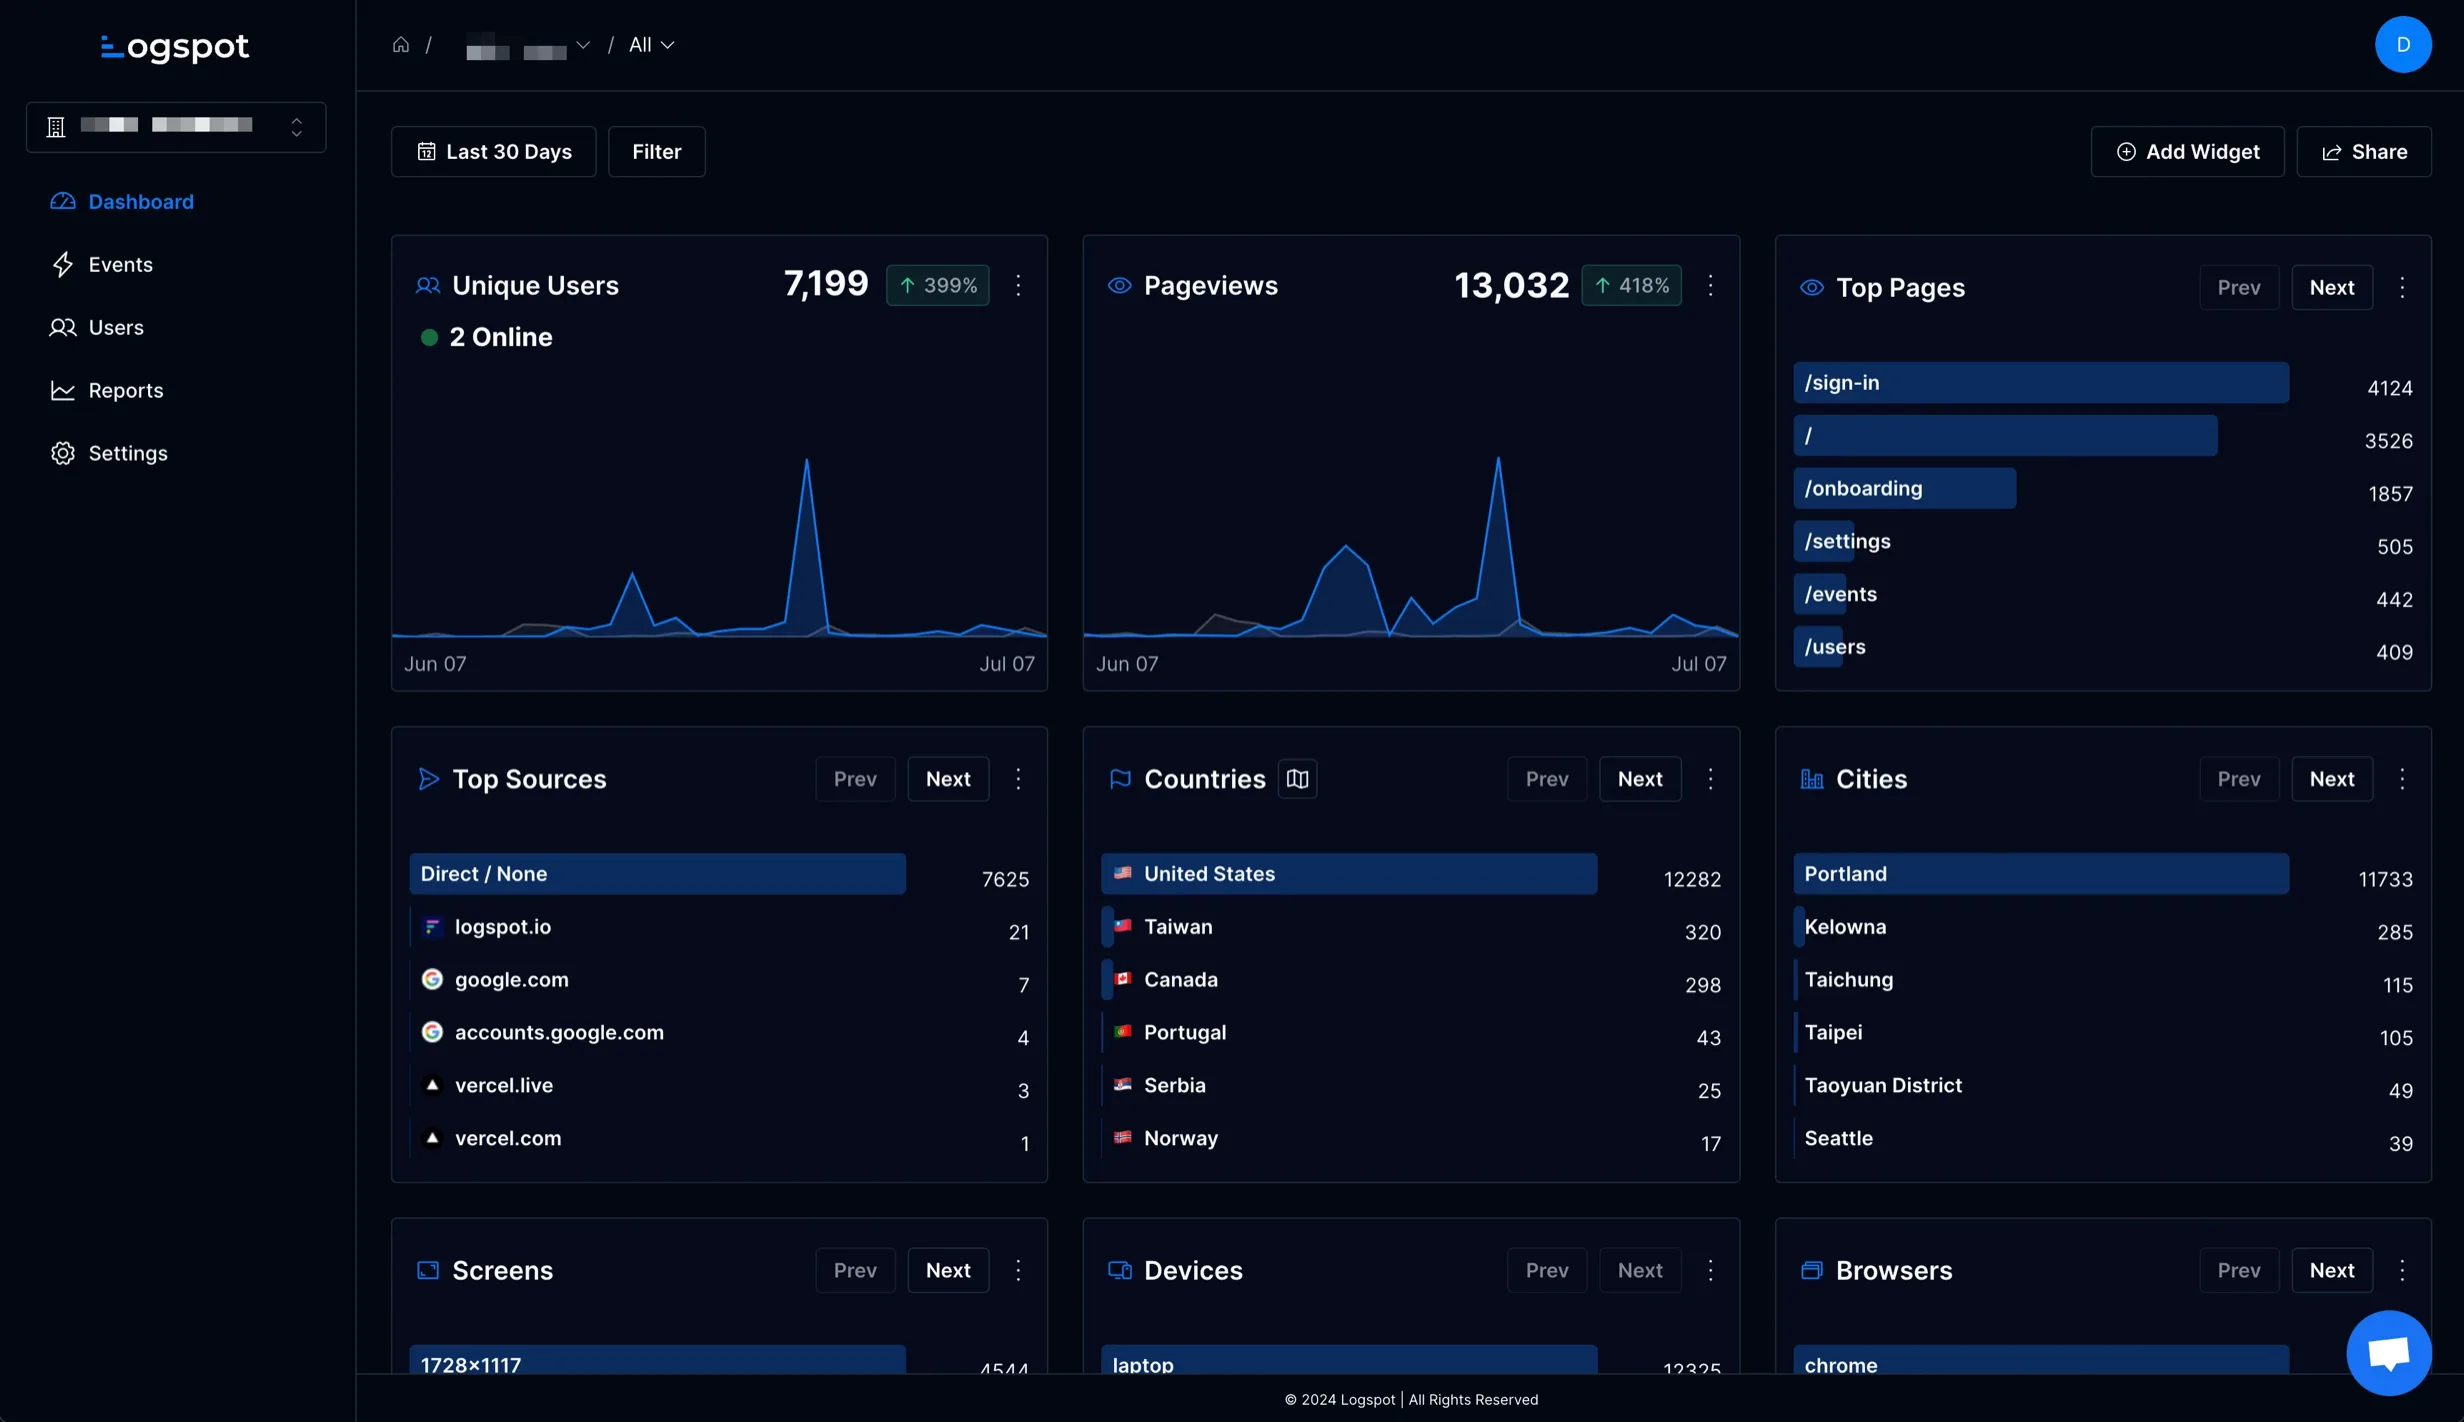
## Integrate Logspot with Your Site/Application
To get started quickly, add one of these two snippets to your site/application and Logspot will start tracking right away.
### Static Sites
The easiest way of integrating your project with Logspot is using our JS script.
```html
```
### Single-Page Applications (SPAs)
For SPA applications, you can use our NPM package [@logspot/web](https://www.npmjs.com/package/@logspot/web)
```js
import Logspot from '@logspot/web';
Logspot.init({ publicKey: 'YOUR_PUBLIC_KEY' });
```
## Send Your First Event
Check our [SDK docs](/docs/sdk/js) to learn how to send your first custom event.
# Dashboard Widgets
URL: /docs/dashboard-widgets
***
title: Dashboard Widgets
description: Add widgets to your project dashboard, including breakdowns that count events or add up a numeric property.
------------------------------------------------------------------------------------------------------------------------
Your project dashboard lives under **Analytics → Dashboard**. Choose **Add Widget** to add a chart, then
pick one of three kinds:
* **Event by Property** breaks one event down by a property, such as signups by country or seats by plan.
* **Multi-Step Funnel** shows how many users move through a sequence of events. See [Funnels](/docs/funnels).
* **Retention Chart** shows how many users come back over time. See [Retention](/docs/retention).
Every widget follows the date range and filters at the top of the dashboard.
## Event by Property
Pick the **Event** to break down, then the **Property** to group it by. The list covers the properties
Logspot records on every event, such as **Location Country**, **Browser**, and **Referrer**. Choose
**Custom** to group by one of your own event properties instead, and type its key.
**Measure** decides what each row shows:
* **Count of Events** shows how many times the event fired for each value. This is the default.
* **Sum of a Property** adds up a numeric property for each value, such as total seats by plan or total
order size by country.
## Sum a Property
Say your app sends an event each time a customer buys seats:
```js
Logspot.track({
event: 'Seats Purchased',
metadata: { plan: 'team', seats: 5 },
});
```
To see how many seats each plan has sold, add an **Event by Property** widget with:
* **Event** set to `Seats Purchased`
* **Property** set to **Custom**, with the key `plan`
* **Measure** set to **Sum of a Property**
* **Property to Sum** set to `seats`
The widget lists each plan with its total, largest first.
**Property to Sum** lists the properties your project's events send. A property you only started sending
recently may not be listed yet. Choose **Use a Property Not Listed** and type the key exactly as your
events send it.
### Which Values Count
Only numbers are added up, including decimals and negative numbers. A value sent as text, such as `"5"`,
is skipped, and so is an event that does not carry the property at all. The caption under the widget
names the property being summed and how many events were skipped, so a tracking call that sends the
wrong type shows up there.
Sums are not available when **Property** is **Acquisition Channel** or **Entry Url**, because Logspot
works those out per session rather than storing them on each event.
A sum adds plain numbers and knows nothing about currency. To total payments, use
[Revenue](/docs/revenue), which keeps each currency separate.
## From the API or an AI Assistant
The [Aggregate events by property](/docs/api-reference/analytics/aggregateByProperty) endpoint takes
`sum_metadata_field` to return the same sums. Each row then carries `total` (the sum), `summed` (how many
events had a number to add), and `count` (all events in the group).
If you have [connected an AI assistant](/docs/mcp), its `aggregate_by_property` tool takes the same
option, so you can ask questions like "How many seats did each plan buy last month?"
## Related
* [Events vs Properties](/docs/events-vs-properties)
* [Funnels](/docs/funnels)
* [Retention](/docs/retention)
* [Revenue Tracking and Attribution](/docs/revenue)
* [Public Dashboard](/docs/public-dashboard)
# Funnels
URL: /docs/funnels
***
title: Funnels
description: Measure how users move through a multi-step flow and find where they drop off.
-------------------------------------------------------------------------------------------
A funnel is an ordered sequence of steps — sign up, create a project, upgrade — and Logspot shows you how many users make it through each one. The gap between two steps is exactly where you're losing people, which is usually the highest-leverage thing to fix.
## How It Works
You define a funnel as a list of **steps**, in order. Each step is one of:
* **Event** — a tracked event by name (e.g. `UserSubscribed`).
* **Page view** — a visit to a specific page.
For each step, Logspot counts the users who completed it along with every step before it, and reports the **drop-off** from the previous step. Each step is also shown as a share of the first step, so you can read overall conversion from the top of the funnel to the bottom.
Funnels are computed from your existing events — there's nothing extra to instrument beyond [tracking the events](/docs/sdk/js) that make up each step. Because funnels run on your raw event data, a funnel updates as events arrive.
## Build a Funnel
Create a funnel in the Logspot dashboard by adding steps in order and choosing an event or page for each. Adjust the date range to compare conversion over time.
## Tips
* Order steps the way users actually experience the flow; the funnel is read top to bottom, so a step in the wrong place makes drop-off hard to interpret.
* Keep each funnel focused on a single outcome rather than trying to describe the whole product in one report.
* Pair funnels with [revenue](/docs/revenue) to see not just where users drop, but where *paying* users drop.
* A funnel tests a path you define. When you want to see the paths users *actually* take, including the ones you didn't anticipate, use [Journeys](/docs/journeys) instead.
## Related
* [Journeys](/docs/journeys)
* [Retention](/docs/retention)
* [Revenue Tracking and Attribution](/docs/revenue)
# Journeys
URL: /docs/journeys
***
title: Journeys
description: See the most common ordered paths users take within a session, before or after any step you pick.
--------------------------------------------------------------------------------------------------------------
A journey report shows the routes people actually take through your site or product, in order, within a
single session. Where a funnel asks how many people completed steps you chose in advance, a journey asks
what people do around a step you care about.
Use it to find paths you did not anticipate, or to check whether the flow you designed is the flow
people take.
## Build a Report
Go to **Analytics → Journeys** and choose **Add Journey Report**. You pick an anchor and explore the
paths around it.
**Anchor type** is either **Event** or **Pageview**, and the anchor value is the specific event name or
page.
**Direction** decides which way the report looks. Forward shows what people did after the anchor, which
answers "where do people go once they land here". Backward shows what they did before it, which answers
"how do people arrive at this step". Backward is the one to reach for when you want to know what leads
to a conversion.
**Depth** controls how many steps out from the anchor the report follows.
Save a report once it is useful, and it will be there next time.
## Reading the Results
Paths are ranked by how many sessions followed each one, so the top rows are the routes most people
actually took. The long tail is always large, because a few steps out almost everyone is doing something
slightly different. The signal is usually in the first two or three steps.
Journeys are scoped to a session, so a path ends when the session does. Someone returning the next day
starts a new journey rather than extending the previous one. See
[Sessions](/docs/sessions) for how a session is defined.
Page URLs are normalized before paths are grouped. The query string and fragment are removed, trailing
slashes dropped, and identifiers inside the path collapsed to `*`, so both numeric ids and UUIDs fold
together. `/orders/1042` and `/orders/1043` both become `/orders/*` and count as the same step, instead
of splitting one real path into hundreds of near-duplicates.
## Journeys or Funnels
Reach for a journey when you do not yet know which steps matter, and for a
[funnel](/docs/funnels) once you do. A common sequence is to anchor a backward journey
on your conversion event to discover how people get there, then build a funnel on those steps to measure
and monitor it.
## Related
* [Funnels](/docs/funnels)
* [Sessions](/docs/sessions)
* [Retention](/docs/retention)
# Public Dashboard
URL: /docs/public-dashboard
***
title: Public Dashboard
description: Share a live, branded view of your project metrics with anyone, no login required.
-----------------------------------------------------------------------------------------------
A public dashboard is a read-only page showing your project's metrics that anyone with the link can
open. Use it for a public status or metrics page, or to give a stakeholder a live view without adding
them to your organization.
## Turn It On
Go to **Analytics → Public Dashboard**. The visibility switch reads **Hidden** until you turn it on, at
which point it reads **Visible** and the page becomes reachable at its share URL.
The URL is shown on the same page. It is derived from the origin you are using, so the link you copy is
the link your audience should open.
## Choose What Appears
**Displayed Events** is a multi-select of the events to show. Pick only the ones you are comfortable
publishing, since anyone with the link can see them. Nothing appears until you select at least one.
**Header** and **Subheader** are free text at the top of the page. The placeholders suggest the shape:
a name like `MyDomain Metrics` and a qualifier like `Last 30 days`.
## Style It
Three colours are configurable, each with a picker that accepts HEX, RGB, or HSL, supports opacity, and
offers an eyedropper:
* **Background Color** for the page behind the content
* **Header Text Color** for the header and subheader
* **Chart Color** for the data itself
Set these to your own brand colours so the page does not look like a generic dashboard.
## What Visitors Can and Cannot Do
Visitors see the metrics for the events you selected. They cannot filter, drill in, change the date
range, see any event you did not select, or reach anything else in your Logspot organization.
Turning the visibility switch back to **Hidden** takes the page down immediately.
## Related
* [Sessions](/docs/sessions)
# Queries
URL: /docs/queries
***
title: Queries
description: Query and filter your event data with advanced search, without writing SQL.
----------------------------------------------------------------------------------------
The query builder answers one-off questions about your raw events. Dashboards and reports are for
numbers you watch repeatedly; Queries is for the question you have once, right now, usually while
debugging or investigating something specific.
Go to **Analytics → Queries**.
## Build a Query
The **Query Builder** takes a few inputs, all optional. Leave one blank and it does not constrain the
results.
**Event** narrows to a single event name. Start here when you know which event you are investigating.
**User ID** narrows to one person, which is the fastest way to answer "what did this user actually do".
**Metadata Path** targets a property inside the event payload. Use dotted notation to reach a nested
value, so a payload of `{"plan": {"tier": "pro"}}` is reached at `plan.tier`.
**Fields** chooses which columns appear in the results table. Add the properties you care about so the
answer is readable rather than a wall of JSON.
## Filtering
Conditions combine the same way they do in the API. Filters inside a group are joined with AND, and
groups are joined with OR, which lets you express "this and that, or this other thing" without nesting
anything by hand.
The available operators are equal, not equal, greater than, greater than or equal, less than, less than
or equal, is null, and is not null. The two null operators take no value, so the value input disappears
when you select one.
For the full reference including request shape, see [Query Filters](/docs/query-filters).
## Results
Results come back as a table with the columns you chose under **Fields**. Because the query runs against
raw events rather than a rollup, you are seeing exactly what was stored, which is what makes this the
right tool for checking whether an event arrived and what it carried.
If a property you expect is missing from the **Metadata Path** suggestions, it is usually because no
event has carried it yet. Send a test event from **Project Settings → Playground** and check again.
## Doing This Programmatically
Everything here is available over the API. See
[Search Events](/docs/api-reference/events/searchEvents) for the endpoint and
[Query Filters](/docs/query-filters) for the filter shape.
## Related
* [Events vs Properties](/docs/events-vs-properties)
* [Query Filters](/docs/query-filters)
* [Customize Events](/docs/customize-tracking)
# Query Filters
URL: /docs/query-filters
***
title: Query Filters
description: Use query filters and filter groups to query by event metadata.
----------------------------------------------------------------------------
Filter groups allow you to do queries by event's metadata.
Filters consist of:
* `filter_groups` - conditions joined with OR
* `filters` - conditions joined with AND
Conditions:
* `field_name` - metadata property
* `operator` - condition operator
* Equal `=`
* Greater than or equal `>=`
* Less than or equal `<=`
* Less than `<`
* Greater than `>`
* Not equal `<>`
* Is null `IS NULL`
* Is not null `IS NOT NULL`
* `value` - condition value
Example:
`All events that have path equal to /mobile-app OR /blog`
```javascript
{
"filter_groups": [
{
"filters": [
{
"field_name": "path",
"operator": "=",
"value": "/mobile-app"
}
]
},
{
"filters": [
{
"field_name": "path",
"operator": "=",
"value": "/blog"
}
]
}
]
}
```
`All events that have path equal to / AND referrer equal to google.com`
```javascript
{
"filter_groups": [
{
"filters": [
{
"field_name": "path",
"operator": "=",
"value": "/"
},
{
"field_name": "referrer",
"operator": "=",
"value": "google.com"
}
]
},
]
}
```
# Retention
URL: /docs/retention
***
title: Retention
description: See how many users come back over time, grouped into cohorts by when they first showed up.
-------------------------------------------------------------------------------------------------------
Retention answers the question every product team cares about: do people come back? Logspot groups your users into **cohorts** — everyone it first saw on the same day — and measures what share of each cohort returned on the days that followed.
## How It Works
A cohort is the set of users who share a first-seen day. For each cohort, retention measures the percentage who came back and did *anything* on a later day:
* **Day 0** is the cohort's first day and is always 100% (everyone was active when they joined).
* **Day 1, 2, 3…** show the share of that same cohort who returned that many days later.
Averaged across cohorts, those points form a **retention curve**. A curve that keeps falling means users try the product and leave; a curve that flattens (stops dropping) means you've found a group of people who keep coming back, which is the signal of product-market fit.
Retention is computed from your events, so there's nothing extra to instrument beyond tracking them. [Identifying users](/docs/identity) makes it more accurate: without it, a person who returns on a different browser or device counts as someone new.
## View Retention
Two places show retention:
* **The dashboard widget.** The **User Retention** widget on your Logspot dashboard plots the curve for the last 30 days of activity, from day 0 through day 30. Hover any point to see the retention percentage and the number of users behind it — a quick pulse without leaving the overview.
* **The Retention report.** For a deeper look, open the **Retention** report in Analytics. There you can configure the cohorts — the date range and which events count as coming back — to answer more specific questions, such as retention among users who completed onboarding, or over a window longer than 30 days.
## Related
* [Identifying Users](/docs/identity)
* [Sessions](/docs/sessions)
* [Funnels](/docs/funnels)
# Revenue Tracking and Attribution
URL: /docs/revenue
***
title: Revenue Tracking and Attribution
description: Connect Stripe or send revenue events, and see which accounts and marketing sources actually drive revenue.
------------------------------------------------------------------------------------------------------------------------
Logspot ties every payment back to the visitor who made it and the marketing source that drove them — so you can answer "which channels and which accounts actually make money," not just which ones get traffic. Revenue flows into the same dashboards as the rest of your analytics; there's no CSV export and no stitching Stripe data to your product data by hand.
Revenue is **account-first**: in B2B a payment is an account event, so Logspot rolls revenue up to the company by default, with the individual user as a drill-down.
## Send Revenue Events
This is the way to record revenue today. Call `revenue` from the browser or your backend:
```javascript
Logspot.revenue(49.99, { currency: 'USD', plan: 'pro' });
```
The amount is in major units (dollars, not cents). Any extra properties (`plan`, `product`, and so on) are stored on the event and available for breakdowns. Because a revenue event flows through the normal pipeline, it is automatically linked to the user, the account, and the marketing source, with no extra setup.
## Connect Stripe
Logspot is on the [Stripe App Marketplace](https://marketplace.stripe.com/apps/logspot). Go to
**Project Settings → Revenue** and choose **Connect Stripe**. You approve a
read-only connection on Stripe's own consent screen, and Logspot reads your payments from then on. There
is no webhook for you to build or maintain.
The connection is strictly read-only. Logspot requests seven read permissions and no write permissions,
so it cannot create, modify, refund, or cancel anything in your Stripe account. Disconnect at any time
from the same page and ingestion stops immediately.
For attribution to work, pass the visitor's Logspot ID into your Stripe Checkout session metadata so Logspot can link the payment to the session that earned it:
```javascript
const session = await stripe.checkout.sessions.create({
// ...your existing checkout config...
metadata: {
logspot_anonymous_id: anonymousId, // from Logspot.getAnonymousId()
},
});
```
Read `logspot_anonymous_id` from the `Logspot.getAnonymousId()` value on the client (or the `lgspt_anonymous_id` cookie) and attach it when you create the session. That single line is the only thing you need to get right. Optionally also pass `logspot_identity_id`, `logspot_session_id`, or `logspot_group_id`.
If a payment arrives without metadata, Logspot still links it to an account by matching the Stripe customer's email domain to a company. Refunds are tracked automatically and net against the original sale.
## Currency
Each payment is stored in its original currency. Set your project's display currency under **Project
Settings → Revenue**, and your organization's reporting currency for cross-project account rollups under
**Settings → Organization → Currency**. Logspot does not convert between currencies; revenue reports are
scoped to the reporting currency.
Send `currency` with every payment. A payment sent without one is stored, but revenue reports leave it out
until you turn on **Count Payments Without a Currency** under **Project Settings → Revenue**. That counts
those payments in the project's display currency, and in organization-wide reports when the display
currency matches the reporting currency. The **Revenue** page shows how many payments were left out and
can turn the setting on in one click. The SDKs also log a console warning when a payment has no currency.
## Attribution
Every payment is attributed to both:
* **First touch** — the marketing source that originally acquired the user or account. Set once and never overwritten.
* **Last touch** — the source of the session that converted.
Both are captured at the identity *and* the account level, and the attribution that was true at the time of the payment is frozen onto it — so a report you run months later still shows the source that earned the sale.
To make first-touch durable across visits, enable [sticky campaigns](/docs/campaigns) in the SDK.
## Reports
The **Revenue** dashboard leads with the account view:
* **Top accounts by revenue**
* **Revenue by first-touch source** and **by last-touch source**
* **Revenue over time**, by channel, and by product/plan
* **ARPA** (per account), **ARPU** (per user), **AOV** (per order), and **LTV** cohorts
Company revenue also appears on each company's detail page, and the per-user revenue tile on profiles.
## Related
* [Campaign Tracking](/docs/campaigns)
* [Identifying Users](/docs/identity)
# API Authentication
URL: /docs/api-authentication
***
title: API Authentication
description: Authenticate requests to the Logspot API with a public key, an API token, or an OAuth client.
----------------------------------------------------------------------------------------------------------
Every request to the Logspot API carries a credential: a **public key** in a header for client-side code,
or, for server-side code, an **API token** sent as a Bearer token. Machine services can also use an
**OAuth client** to mint short-lived tokens. API tokens and OAuth clients carry **scopes** that decide
what they may do.
## Find Your Keys
**Public key.** In the Logspot dashboard, go to **Project Settings → Integrations**. The **Project Key**
section shows your **Public Key**, prefixed `pk_`. It is safe to include in client-side code.
**Secret key.** Server-side keys are API tokens you create on demand. In **Integrations → AI & API Access
→ API Keys & OAuth**, or the **API Keys** section of a project's Integrations tab, click **Create API
Key**, choose its scopes, and copy the secret once. Secret keys are shown only at creation; afterward the dashboard shows
just the last four characters. If you lose one, create a new key and revoke the old.
A secret key is prefixed `sk_` and is server-side only. Never expose it in a browser, a mobile app, or a
public repository. Store it in an environment variable or a secret manager, for example
`LOGSPOT_SECRET_KEY`, rather than hardcoding it.
A key can be scoped to **one project** or to the **whole organization**. A key created from a project's
Integrations tab is scoped to that project, which is what server-side ingestion needs. Keys created under
**Integrations → AI & API Access → API Keys & OAuth** can be organization-wide, for reading across every
project.
## Authenticate a Request
The `pk_` / `sk_` prefix is part of the key and the API will reject the request without it.
Server-side, send an API token as a Bearer token:
```bash
curl https://api.logspot.io/v1/track \
-H "Content-Type: application/json" \
-H "Authorization: Bearer sk_a1b2c3d4e5f6" \
-d '{"name": "Signup Completed", "user_id": "user_123"}'
```
Client-side, send the public key in the `x-logspot-pk` header:
```bash
curl https://api.logspot.io/v1/track \
-H "Content-Type: application/json" \
-H "x-logspot-pk: pk_a1b2c3d4e5f6" \
-d '{"name": "Page Viewed"}'
```
A legacy project secret can still be sent as `x-logspot-sk: sk_...` and behaves like a project-scoped API
token. The older unversioned paths (`/track`) keep working as aliases of `/v1/...`.
In Postman or Insomnia, set Authorization to **Bearer Token** and paste the full `sk_...` value.
## Which Key to Use
Ingestion is addressed by the credential: the key names the project, so ingest calls never take a project
id. Reads of one project's data address it in the path, `/v1/projects/{project_id}/...`; an organization
key can read any project in the organization, a project key only its own, and the project in the path must
match. Organization-level operations (privacy requests, companies, identities, members) are flat and
need an organization key.
| Endpoint | Public key | Project key | Organization key |
| -------------------------------------------------------------------- | ---------- | ----------- | ---------------- |
| `/v1/track`, `/v1/identify`, `/v1/group`, `/v1/consent` | Yes | Yes | No |
| `/v1/projects/{project_id}/search-events` | No | Yes | Yes |
| `/v1/projects/{project_id}/analytics/*` | No | Yes | Yes |
| `/v1/projects/{project_id}/revenue/*` | No | Yes | Yes |
| `/v1/privacy-requests` (deletion and export requests) | No | No | Yes |
| `/v1/companies/*`, `/v1/identities/*`, `/v1/projects`, `/v1/members` | No | No | Yes |
Each key also carries scopes (for example `events:write` or `analytics:read`); a request needs the matching
scope as well as the right key type.
Requests made with the public key are rate limited per IP address. Requests made with an API token are
rate limited per key.
If a request returns a `401`, check that the header value still carries its `pk_` or `sk_` prefix, that
the endpoint accepts the key type you used, and that the key belongs to the project you are writing to.
## Scopes
When you create an API token or an OAuth client you grant it scopes. A request needs the scope its
endpoint requires (a `403` means the credential is valid but missing that scope). Ingest scopes work with
a project token; read scopes work with a project or organization token, except the organization-wide
reads (companies, identities, members) which need an organization token. Privacy request scopes always
need an organization token.
**API Access is a Pro plan feature.** Reading data with an API token or OAuth client requires the Pro or
Enterprise plan; on Free and Essentials those requests return `403` with a
message naming the plan. Ingest scopes work on every plan, and so does the AI assistant connection
(MCP), because it acts as a signed-in person rather than a machine credential.
| Scope | Grants | Plan |
| ------------------------ | ------------------------------------------------------------------------------------------------- | ---- |
| `events:write` | Send events via `/track` | All |
| `identities:write` | Identify users via `/identify` | All |
| `groups:write` | Associate users with groups via `/group` | All |
| `consent:write` | Record consent via `/consent` | All |
| `events:read` | Search raw events via `/search-events`, including any amounts sent on them | Pro |
| `analytics:read` | Read analytics counts, aggregates, and metrics; property totals can add up amounts sent on events | Pro |
| `revenue:read` | Read revenue metrics, attribution, and cohorts, plus the revenue on company and user metrics | Pro |
| `identities:read` | Read identity profiles, sessions, and activity (personal data) | Pro |
| `privacy_requests:read` | Read the status of privacy requests (DSR/DSAR) | All |
| `privacy_requests:write` | File deletion and export privacy requests | All |
| `projects:read` | List the organization's projects | Pro |
| `organization:read` | Read organization members and settings metadata | Pro |
## Machine-to-Machine Access (OAuth Clients)
For a backend service that should not hold a long-lived secret key, create an **OAuth client** in
**Integrations → AI & API Access → API Keys & OAuth**. You choose a name and the scopes the client may ever use;
Logspot returns a client id and a client secret once. The client then exchanges them for short-lived
access tokens using the standard `client_credentials` grant, naming the REST API as the resource:
```bash
curl https://api.logspot.io/api/auth/oauth2/token \
-u "$LOGSPOT_CLIENT_ID:$LOGSPOT_CLIENT_SECRET" \
-d grant_type=client_credentials \
-d scope="analytics:read events:read" \
-d resource=https://api.logspot.io/v1
```
Use the returned `access_token` as a Bearer token exactly like an API token:
```bash
curl https://api.logspot.io/v1/companies/top \
-H "Authorization: Bearer $ACCESS_TOKEN"
```
A few rules follow from how these tokens are issued:
* A token can only carry scopes inside the client's ceiling; asking for more returns `invalid_scope`.
* Tokens are bound to the REST API resource. A token minted for the MCP resource is rejected here, and
a REST token is rejected at `/mcp`.
* An OAuth client is organization-scoped, so it can read across projects but cannot ingest events
(ingestion needs a project key). Because an owner or admin creates it, it satisfies owner-or-admin
requirements by construction, so the companies, revenue, and identity endpoints are reachable.
* Rotate the secret from the same page; the previous secret stops working immediately.
## Migrating from a Project Secret Key
Older integrations used a per-project secret sent as `x-logspot-sk`. That still works and is treated as a
project-scoped API token, so nothing breaks. When you next touch an integration, prefer an API token:
* Create a token in **Integrations → AI & API Access → API Keys & OAuth** (organization-wide) or a
project's Integrations tab (project-scoped), and send it as `Authorization: Bearer sk_...`.
* A token is scoped and revocable, and you can hold several at once, so you can rotate without downtime
and give each integration only the scopes it needs.
* Two behaviors moved to the organization level and no longer accept a project secret: **privacy requests**
(`/v1/privacy-requests`, formerly the project `/privacy/*` routes) need an organization token, and the
cross-project reads (companies, identities, members) always did.
* New projects no longer generate a secret key at all. Create an API token instead.
## Related
* [Track Events](/docs/api-reference/events/trackEvent)
* [Identifying Users](/docs/identity)
# How Tracking and Identity Works
URL: /docs/how-it-works
***
title: How Tracking and Identity Works
description: The mental model behind Logspot — anonymous IDs, user IDs, sessions, groups, and consent gating, and exactly what data leaves the browser.
-------------------------------------------------------------------------------------------------------------------------------------------------------
This page explains how Logspot turns raw browser activity into people, sessions, and accounts — and exactly what data leaves the visitor's browser. It doubles as a transparency reference: there are no hidden identifiers and no fingerprinting.
## The Core Identifiers
Every event Logspot records is tied to two IDs:
| ID | Set by | Lifetime | Purpose |
| ---------------- | ------------------------------------- | ------------------------------------------------------------- | ------------------------------------------------------------------- |
| **Anonymous ID** | The SDK, automatically | First-party cookie, **\~12 months** by default (configurable) | Links a visitor's events together before they tell you who they are |
| **User ID** | You, via [`identify()`](/docs/sdk/js) | Stable for the life of the account | Links events to a known person across devices and sessions |
When the script loads, the SDK calls `ensureAnonymousId()` — it reads the `lgspt_anonymous_id` first-party cookie, or generates a new random ID if there isn't one. No IP-based fingerprinting. No third-party cookies. You can read the current value with `Logspot.getAnonymousId()`.
The \~12-month default lifetime is chosen to respect most privacy laws and regulations — well under the limits typical analytics tools push with 2-year cookies. You can shorten it with the SDK's [`cookieExpirationInSeconds`](/docs/sdk/js) option if you operate in regions that restrict the consent window further (some require as little as 6 months).
## Anonymous → Identified
A visitor starts anonymous. Their pageviews and events all carry the anonymous ID. When they do something that tells you who they are — sign up, log in — you call:
```js
Logspot.identify('user_123', { plan: 'pro' });
```
From that point the SDK attaches the user ID to every event. On the server, Logspot **merges** the anonymous history into the identified person, so the pre-signup activity isn't lost — the visitor who browsed your pricing page last week and the user who just upgraded are the same person.
`identify()` sends the anonymous ID alongside the new user ID (`POST /identify`), plus any `traits` you pass (e.g. `plan`, `name`). Traits describe the person; **events** describe what they did. See [Events vs Properties](/docs/events-vs-properties) for where each piece of data belongs.
On logout, call `Logspot.reset()` — it clears the user ID and super properties and rotates the anonymous ID so the next visitor on a shared device starts clean.
### Secure Mode
If you don't want anyone to be able to claim an identity by guessing a user ID, you can verify identities server-side. Pass a short-lived token your backend signs:
```js
Logspot.identify(
'user_123',
{ plan: 'pro' },
{
identityVerification: { token: serverSignedToken },
},
);
```
Unverified writes follow a "restrict, never expand" rule on the backend: consent *denials* and privacy signals always apply, but consent *grants* for a user ID require a valid token.
## Sessions
You don't create or manage sessions in the SDK. Logspot derives them **server-side** from the stream of events — grouping a visitor's activity into sessions based on timing and inactivity. This keeps the client lightweight and means session logic can improve without an SDK upgrade.
## Groups
People belong to accounts, teams, or workspaces. Logspot links a user to a group (a company, team, or workspace) through the [Group API](/docs/groups) or a `group_id` on a raw track event, so you can roll product usage up from individual users to the company they belong to. That is essential for B2B analytics, where the buying unit is the account, not the seat.
## Consent Gating
Logspot is consent-aware end to end. Every event carries a consent snapshot, stamped by the SDK *after* your `eventMapper` runs so it can't be clobbered:
* **`privacy_categories`** — the analytics / functional / marketing categories the visitor has (or hasn't) granted.
* **`privacy_signals`** — browser signals like Global Privacy Control (GPC) and Do-Not-Sell.
* **`consent_source`** — what set the current state (your `setConsent` call, a CMP, etc.).
You report consent state with [`setConsent()`](/docs/sdk/js) and read it back with `getConsent()`:
```js
Logspot.setConsent({ analytics: true, marketing: false });
```
How strictly events are held depends on your org's **consent behavior**:
* **`notRequired`** (default) — events send immediately; the snapshot is recorded for the record.
* **`express`** — events are queued in memory until the first consent snapshot exists, then flushed (or dropped if analytics was denied).
Browser **Do-Not-Track** is also respected: if a visitor sends a DNT header and you've enabled `enableBrowserDNT`, the SDK disables itself entirely. See [Do Not Track](/docs/dnt).
## What Actually Leaves the Browser
Each event is a single `POST https://api.logspot.io/i` with the public key in the `x-logspot-pk` header. The payload is the event name, the anonymous/user IDs, the page URL and referrer (campaign params stripped from the stored URL), screen size, language, hostname, your `metadata`, and the consent stamps above. There is no canvas fingerprinting, no battery/font enumeration, and field values are **never** read by autocapture — form and input capture record metadata only, and sensitive fields (passwords, OTP, credit-card autofill) are skipped.
## Next Steps
* [Events vs Properties](/docs/events-vs-properties) — model your data correctly
* [Build a Tracking Plan](/docs/tracking-plan) — decide what to track
* [JS SDK reference](/docs/sdk/js) — the full API
* [Do Not Track](/docs/dnt) and [Cross-domain tracking](/docs/cross-domain)
# Projects and Domains
URL: /docs/projects
***
title: Projects and Domains
description: Create a project, set the domains it accepts events from, and give it a readable slug.
---------------------------------------------------------------------------------------------------
A project is one tracked property: a website, a product, or an environment. Each project has its own
keys, its own settings, and its own data.
## Create a Project
Open the project switcher and choose **Add New Project**. You provide a **Project Name** and at least
one entry under **Tracking Domains**.
The domains are not optional. A project with no domains would accept events from any origin, so the
dialog blocks submission with **Add at least one domain to continue** until you add one.
The dialog shows a running count of root domains used against your plan's limit. Subdomains of a domain
you already listed do not count again, so `app.example.com` and `www.example.com` together consume one
root domain, not two. If adding a domain would exceed the limit, the dialog says so and links to
**Settings → Billing**.
## Tracking Domains
Manage them later at **Project Settings → Domains**. The list is the allowlist of origins that may send
events with this project's public key. Requests from anywhere else are rejected, which is what stops
someone from copying your snippet onto another site and polluting your data.
Add every origin you actually serve from, including staging and preview environments if you want data
from them.
Projects created before domains became mandatory can still have an empty list. Those accept events from
any origin, and **Project Settings → General** shows a warning saying so, with a link to fix it. If you
see that warning, add your domains.
## Name and Slug
**Project Settings → General** holds the **Project Details**.
**Project Name** is the display name, and you can change it whenever you like.
**Slug** is the readable identifier used in URLs, in place of a long project id. It accepts lowercase
letters, numbers, and hyphens. Slugs are unique within your organization, so if the one you want is
taken you will get an error on the field and can pick another.
## Keys
Each project has its own **public key** (safe for the browser) under **Project Settings → Integrations**,
where you also create **API tokens** for server-side calls. Keys and tokens are never shared between
projects, so an environment separated into its own project is genuinely isolated. Organization-wide tokens
for reading across projects live under **Integrations → AI & API Access → API Keys & OAuth**. See
[API Authentication](/docs/api-authentication).
## Related
* [API Authentication](/docs/api-authentication)
* [Cross-Domain Tracking](/docs/cross-domain)
* [How Tracking and Identity Works](/docs/how-it-works)
# Actions and Data Credits
URL: /docs/actions-data-credits
***
title: Actions and Data Credits
description: How Actions and Data Credits are metered, topped up, and spent.
----------------------------------------------------------------------------
Two meters govern what [Actions](/docs/actions) can do, and they move independently.
**Actions** is a value-based unit. Each task type costs a fixed number of Actions, set by what the task
is worth rather than what it costs to run. Your plan includes an allowance each month.
**Data Credits** is a cost-based unit covering the real expense of a run: model tokens for AI tasks, and
the provider fee for data lookups. You buy these in packs.
Each notification you send uses 1 Action and no Data Credits.
Both live on **Settings → Billing**.
## Where Credits Go
AI tasks reserve a conservative estimate before running, then settle to what the run actually cost once
the tokens are counted. You are charged the real figure, not the estimate. If a task fails after being
charged, both meters are refunded.
Data lookups charge a flat rate per lookup. The rate does not change based on which provider served the
match, so a lookup costs the same whichever source answered it.
**Data Credits Used This Period** breaks spend down by what consumed it, so you can see whether your
credits went to enrichment, prospect research, lead qualification, or something else.
**Actions Used This Period** does the same for the Actions meter.
## Topping Up
**Buy Data Credits** purchases a pack. Larger packs carry a better rate.
**Enable auto-refill** buys the smallest pack that covers you whenever your balance runs out, so a
long-running automation does not stall overnight. Set a **Monthly spend cap** to bound what auto-refill
can charge in a billing cycle. Auto-refill never exceeds that cap.
You can also add a pack of credits during checkout when you start or change a plan, and during
onboarding, where the step is skippable.
## Bonus Data Credits
Paid plans earn Data Credits back on settled invoices, granted automatically when an invoice is paid.
The amount is a share of your base subscription spend and appears on the plan cards and the change-plan
sheet as a monthly figure, so you can see what a plan earns before you choose it.
Two details worth knowing. Discounts are netted out first, so a fully comped subscription earns nothing.
Free and Enterprise plans do not accrue bonus credits.
Bonus credits arrive in the same wallet as purchased credits and appear in the ledger as **Bonus Data
Credits**.
## Extra Actions
If you consistently run out of Actions before the month does, **Extra Monthly Actions** is a recurring
add-on that raises your included allowance. Switch tiers or remove it at any time.
## Running Out
Notifications keep sending when your Actions allowance runs out. They are still counted and appear
under **Actions Used This Period**, so you never miss an alert because of a meter.
When the wallet cannot cover a run, the action is blocked rather than run and billed later. Enrichment
buttons and auto-enrich toggles switch to an **Add Data Credits** prompt, and a run attempted over the
API returns an out-of-credits error. Topping up unblocks it immediately; nothing is lost.
## Related
* [Actions](/docs/actions)
* [Company Enrichment](/docs/enrichment)
# Actions
URL: /docs/actions
***
title: Actions
description: Set up a task once and reuse it, from a Slack notification to an AI-researched account brief.
----------------------------------------------------------------------------------------------------------
An Action is a task you configure once and reuse. Sending a Slack message when a signup lands,
enriching a company from its domain, scoring a lead against your ICP, mailing a weekly digest: all of
these are actions.
You add one from the catalog, configure it, and it lives in **Your Actions** where you can run, edit,
pause, or delete it.
> Actions replace the older Triggers and Robots. Any trigger you had was converted into a **Send
> Notification** action with the same event and the same destination, so existing notifications keep
> working. Nothing delivers twice.
## What an Action Is Made Of
Read it left to right: sources, then what happens, then where the result goes.
**Sources** are where the action reads from. Today that means your projects.
**Schedule and triggers** decide when it runs. A **schedule** runs it on a cadence you set with a cron
expression. **Triggers** run it when something happens: an event
arrives, or Logspot records a signal. Tasks that support it can also be run by hand at any time.
**Task** is what it does, and is the catalog entry you picked.
**Agents** are the reasoning, for tasks that need it. An action can have none, one, or several. A
template digest has no agent. Build Company Profile has two that work together.
**Context** is what an AI task knows: your Company Profile, plus any additional instructions for that
one action.
**Destinations** are where the result goes: Slack, Discord, email, Telegram, a webhook, Clay, or HubSpot.
You set them on the **Destinations** tab. An AI task can also skip delivery and keep its
result in the Activity Log.
## Send Notification
This is the one most people want first. It uses 1 Action per notification, no Data Credits, and is
included on the Essentials plan and up.
1. Go to **Actions → Browse Catalog**, choose **Send Notification**, and click **Add & Configure**.
2. On the **Basics** tab, choose **Add Trigger** and enter the event name to match, such as
`Signup Completed`, or pick a signal.
3. On the **Destinations** tab, set **Destination** to Slack, Discord, Email, Telegram, Webhook, Clay, or
HubSpot, and save.
4. In **Your Actions**, open the action's menu and choose **Send Test** to check the destination. A
test webhook carries an `x-logspot-test: true` header, so your endpoint can tell it from a real
delivery.
When a matching event arrives, Logspot applies the consent gate and delivers. Delivery fires once per
event even though the underlying queue can deliver a message more than once, so you will not get
duplicate alerts.
Each notification uses 1 Action, however many destinations it reaches. Retries and **Send Test** are
free, a notification that could not be sent to any destination costs nothing, and notifications keep
sending when your Actions allowance runs out.
## Triggers and Cooldown
An action can have up to ten triggers, and any one of them starts it. Each trigger is one of these:
* **Event** fires when an event with that name arrives.
* **Signal** fires when Logspot records a signal of that type. Under **Which Accounts**, choose
**Target Accounts Only** to react only to signals about your target accounts, or **All Accounts**.
Signal triggers are being enabled account by account, alongside [Signals](/docs/signals).
**Cooldown** stops overlapping triggers from repeating the same work. The choices are **Every
Occurrence**, **15 Minutes**, **1 Hour**, **24 Hours**, and **7 Days**. With 1 Hour, an action runs
about once per company in each hour, however many of its triggers fire. Every Occurrence runs on each
match, and a notification for an event Logspot cannot tie to a company always sends. Send Notification
starts at Every Occurrence, and AI tasks start at 1 Hour.
## AI Tasks on Triggers
Prospect Research, Lead Qualification, and Outreach Draft can run from triggers. When a trigger fires,
the task runs for the company behind the event or signal and sends its result to the action's
destinations. Each run spends credits, the same as running it by hand.
A triggered AI task only runs when Logspot knows the company and has its name or website, and each AI
action runs at most 100 times a day from triggers. The cooldown applies too, so a busy account is
researched once per window instead of once per matching event.
> Chaining, which passed a signal on to an AI task, has been removed. Add a signal trigger to the AI
> action instead. Existing chains were converted this way automatically, with the cooldown set to
> Every Occurrence so each signal still runs the task once. An AI action that was set to run on an
> event or signal used to deliver only that event or signal, so it was converted to a Send Notification
> action that keeps doing exactly that, without spending credits.
## The Catalog
The catalog holds thirteen task types. Eight appear in **Browse Catalog**; the rest run from the surface
they belong to.
| Task | What it does |
| -------------------------- | -------------------------------------------------------------------------------------------------- |
| Send Notification | Send a message to Slack, Discord, email, Telegram, a webhook, Clay, or HubSpot when an event fires |
| Weekly Summary (Template) | A deterministic weekly activity digest |
| Weekly Summary (+ AI) | A weekly digest with an AI-written narrative |
| Enrichment Digest (Weekly) | A weekly summary of what was enriched and identified |
| Prospect Research | Research a prospect company and its contacts into a brief |
| Lead Qualification | Score a lead against your ICP |
| Outreach Draft | Draft a cold email and a LinkedIn sequence |
| Weekly GTM Digest | Narrate the week's signals for each target account |
Five more exist but run from their own surfaces rather than the catalog: Build Company Profile and
Account Watch run from Profiles and Target Accounts, Company Lookup and Person Lookup run from the
enrichment surfaces, and Company Visitor Identification runs as visits arrive, in the projects you turn
it on for under Actions → Enrichment.
You only see catalog entries your organization has access to, so your catalog may be shorter than this
list.
## Setting One Up
Pick a task from **Browse Catalog** and open its card with **Add & Configure**. The Set Up Action dialog
has tabs, in order: **Basics** (name, triggers, cooldown), **Sources** (the project scope, your whole
organization or specific projects), **Destinations** (where the result goes), **Watched Accounts** (Account
Watch only), **Agents**, and **Context**. Add triggers or a schedule on **Basics**, choose the scope on
**Sources**, and for AI tasks set the Company Profile and any additional instructions on **Context**.
Saving an action does not run it. **Run Now** is a separate, explicit button, and it appears only for
manual tasks that can run straight from their saved configuration.
**Your Actions** has two tabs. **Library** lists your saved actions, with a scope column so you can tell
organization-wide actions from project-specific ones. Actions of the same type are grouped into one row
that expands to the individual actions, and a group surfaces any problems first, so a failure is not hidden
when the group is collapsed. The **Last Run** column shows each action's most recent run, including why a
run failed. **Activity Log** is the run history, and each run opens to its detail.
## The Company Profile
AI tasks work from a Company Profile: structured intelligence about a company, including its ICP, value
propositions, and competitors.
**Our Profiles** describes your own company. One is the default, and that is the context fed to AI
agents automatically. **Target Accounts** describes the companies you sell to, in the same shape without
your strategy overlay.
You build or refresh a profile from a website, so refreshing needs the profile to be linked to a real
one. If it is not, rebuild it from Profiles instead.
## What Costs Credits
Two meters move independently.
**Actions** is a value-based unit. Each task type has a fixed Actions cost.
**Data Credits** is a cost-based unit, covering the real model and data cost of a run. AI tasks reserve
a conservative estimate first, then settle to what the run actually cost. If a task fails after being
charged, both meters are refunded.
A notification uses 1 Action and no Data Credits. AI tasks and data lookups use both meters. When an AI
task delivers its result, the delivery is part of that task's cost. A write to HubSpot counts as a
notification: 1 Action.
Your organization's first Company Profile build is free.
See [Actions and Data Credits](/docs/actions-data-credits).
## Consent
Every action declares the consent it requires before it runs. An action that sends data onward for
advertising only runs for events carrying marketing consent. Logspot checks the event's recorded
permissions and the person's current consent before executing, so an automation never acts on data the
person did not allow. See [Consent Management](/docs/consent).
## A Note on the Notify Flag
Older SDK examples set `notify: true` on a track call to fire a notification without matching an event
name. Nothing reads that flag now. It is still accepted so SDKs sending it do not error, and it is still
stored, but it fires nothing. Match on the event name instead when setting up a Send Notification
action.
## Related
* [Receiving Webhooks](/docs/receiving-webhooks)
* [Data Credits](/docs/actions-data-credits)
* [Consent Management](/docs/consent)
# Enrichment
URL: /docs/enrichment
***
title: Enrichment
description: Fill in company firmographics and professional traits automatically, from a domain or an email.
------------------------------------------------------------------------------------------------------------
Enrichment fills in the details you did not collect. Give Logspot a company domain and it returns
firmographics such as industry, size, and location. Give it a work email and it returns that person's
professional traits.
There are two lookup types.
**Company lookup** takes a domain. Use it to turn a bare domain into an account you can qualify.
**Person lookup** takes an email address, and the result attaches to that person's identity.
## Turning It On
Open **Actions → Enrichment**. **Auto-Enrich Companies** enriches a company's
attributes when a new domain first appears. **Auto-Enrich People** enriches a person's professional
traits when they first identify by email. Both are off by default.
Leave auto-enrich off if you would rather enrich selectively, and use the manual route instead.
## Enriching One Record
Open a company from **Analytics → Companies** and use the **Enrich** button. This is the right approach
when you only care about a handful of accounts, since it spends nothing on companies you are not
pursuing.
## What It Costs
Each lookup type has a fixed cost in Data Credits and Actions, shown on the action's detail view. The
rate for a lookup type is the same every time, regardless of where the match came from.
A lookup that finds nothing costs nothing. You are only charged for a match.
If your wallet cannot cover a lookup, the Enrich button and the auto-enrich toggles switch to an **Add
Data Credits** prompt rather than running and billing you later. See
[Data Credits](/docs/actions-data-credits).
## Getting Told About New Accounts
**Notify on New Identifications** sends a message the first time a company or person is identified in a
project. Choose where under **Send To**: Slack, Discord, email, Telegram, or a webhook. Each notification
uses 1 Action and no Data Credits, however many destinations it reaches.
This is the setting that turns enrichment from something you check into something that reaches you.
A new target-shaped company landing on your pricing page is worth knowing about the same day.
Person notifications respect that person's consent, and a blocked send is recorded rather than silently
dropped.
## Consent
Enrichment runs on companies and people you already know about. What you may do with an enriched record
downstream, particularly for advertising or for sharing with a third party, is governed by the consent on
file, which travels with the data. See [Consent Settings](/docs/consent-settings).
## Data Sources
Logspot uses waterfall enrichment, including its own web research for company lookups and the
[People Data Labs Free Company Dataset](https://docs.peopledatalabs.com/docs/free-company-dataset),
licensed under [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/), which Logspot has normalized
and modified. Each lookup checks the sources in order and keeps the first match.
## Related
* [Companies](/docs/companies)
* [Actions and Data Credits](/docs/actions-data-credits)
* [Consent Settings](/docs/consent-settings)
# Search Console
URL: /docs/search-console
***
title: Search Console
description: Join Google Search Console's search data to the companies that landed on each page.
------------------------------------------------------------------------------------------------
Search Console tells you which searches bring people to your site. It cannot tell you who those people
are. Logspot takes the pages Google says are earning clicks and shows which companies started a visit on
those pages in the same period, so a keyword stops being an anonymous number and starts pointing at
accounts you can act on.
## Connect a Property
Go to **Project Settings → Search Console** and connect your Google account, then choose a property.
Logspot lists the properties your Google account already has access to, and suggests the ones matching
the project's tracking domains first.
Logspot requests read-only access. It never writes to Search Console, submits sitemaps, or changes
anything in your property.
Once connected, the report appears at **Analytics → Search**.
## Reading the Report
The page has three parts, and they do not come from the same request.
**The totals** for clicks, impressions, CTR, and average position come from a request with no breakdown,
which is how Google returns a true total.
**The Pages tab** groups Google's rows by page and joins each one to the companies that landed there.
**The Queries tab** groups the same rows by query, and splits each page's companies and revenue across
the queries that drove it.
CTR is calculated as total clicks divided by total impressions rather than averaged across rows, and
average position is weighted by impressions. Averaging rows would let a single-impression row count as
much as one with ten thousand.
### Why the Table Does Not Add up to the Total
Google returns its top rows for a breakdown, not every row, and only gives a true total when you ask
without one. Logspot shows Google's real total on the cards and Google's top rows in the table, rather
than summing a sample and calling it a total. A gap between the two is expected and is not a bug.
## How the Company Join Works
Google never identifies a searcher, so the join happens at the page level, not the click level.
For each page in the breakdown, Logspot counts the distinct companies whose Google organic session
started on that page inside the same date window. Both sides of the join are normalized the same way:
the query string and fragment are removed and a trailing slash dropped. The host is kept, so
`example.com/docs` and `www.example.com/docs` are different pages, exactly as Search Console reports
them.
Companies and revenue are scoped to Google organic visitors, mirroring how Google itself pairs Search
Console with analytics. Paid clicks are excluded, detected both from a paid `utm_medium` and from the
click identifiers Google Ads adds to a landing URL automatically.
This is not click-level attribution, and it should not be described as such. "Google organic visitors
who started on this page" is the honest ceiling.
### No Match
`No match` means no session started on that page in the window, which is different from a page that had
zero identified companies. Pages Logspot has no data for are counted and reported separately rather than
being shown as zero.
## Estimates and the Tilde
A page's companies and revenue are divided across the queries that drove it, in proportion to each
query's share of that page's clicks.
A `~` in front of a number means the figure is a split rather than a count. It disappears when a query
was the only one driving every page it touched. Hovering the cell shows what share of the query's clicks
the estimate rests on.
An em dash (—) means all of that query's clicks landed on pages with no match, so there is nothing to
attribute.
Two things to understand about query-level numbers. The companies figure can exceed the number of
distinct companies you have, because each page contributes its own count and one company visiting three
pages counts three times. It answers how much company activity sits behind a query, not how many
different companies. And a single click can carry a whole page's revenue, since page revenue accrues
from all of that page's Google organic customers. That is the estimate working as designed, which is why
it is marked.
## Revenue
Page revenue is grouped by the first-touch landing page. A customer who first arrived from a Google
search in January and paid in August is credited to their January landing page.
So page revenue means revenue from customers Google search originally delivered to that page, not sales
that happened after a search this week.
## Dates and Limits
Search Console reports days in Pacific time. Rather than shifting Google's data, Logspot converts your
window to the same Pacific calendar days, so both halves of a row cover the same hours.
Google's most recent days are still being processed when they are fetched, which is why the ranges on
offer stop at six months rather than a year. Where Google marks data as still incomplete, the report
says so.
The report covers a date range of up to 200 days, requests the API maximum of 25,000 rows, and displays the
top 100 per tab. Results are cached briefly, so two loads in quick succession return the same numbers.
## Related
* [Acquisition Channels](/docs/acquisition-channels)
* [Companies](/docs/companies)
* [Revenue Tracking and Attribution](/docs/revenue)
# Signals and Target Accounts
URL: /docs/signals
***
title: Signals and Target Accounts
description: Get told when an account you care about does something worth acting on.
------------------------------------------------------------------------------------
A signal is a notable thing an account did, surfaced to you instead of waiting for you to go looking.
Find them at **Actions → Signals**, newest first, with a timeline per account.
Signals come in two kinds. Internal signals are derived from behavior Logspot observed on your own site
or product. External signals come from research about the company.
## Target Accounts
Most signals only fire for target accounts, which is deliberate. Alert fatigue is the usual failure of
this kind of feature, and the fastest way to cause it is to alert on everyone.
Target Accounts live under **Actions → Profiles**. Add an account by promoting a company from
**Analytics → Companies**, or by saving one from research.
## Internal Signals
| Signal | Fires when |
| ---------------------- | ------------------------------------------------------------------------------------------ |
| Target Account Visited | Someone from a target account visits your site |
| High-Intent Page Visit | A target account visits a page that suggests buying intent, such as pricing, demo, or docs |
| Return Visit | A target account comes back within a week of a previous visit |
| Usage Spike | A target account's activity jumps well above its own recent norm |
| New ICP-Fit Company | A newly enriched company matches your ICP |
Usage Spike compares an account's trailing week against its own trailing four-week average, and requires
a floor of activity before it fires. Without that floor, a small account going from two events to eight
would register as a spike every time.
New ICP-Fit Company is the one signal that is not limited to target accounts, since its whole job is to
find accounts you have not flagged yet. It fires once per company, ever.
## External Signals
External signals describe things happening at the company rather than on your site: **Funding**,
**News**, **Leadership Change**, **Hiring**, and **Product Launch**.
These come from Account Watch, a scheduled research refresh you enable on a target account. It looks for
changes and records what it finds as signals.
## Custom Rules
The built-in signals cover common patterns, but you can also define your own. A rule watches for a
threshold on an account and fires the **Custom Rule Matched** signal when an account crosses it. Manage
rules from **Actions → Signals**.
A rule has one to five conditions, and you decide whether an account must meet **all** of them or **any**
one. Each condition measures:
* **Events**, the count of matching events.
* **Identified users**, the number of distinct people.
* **Growth**, the current window against the account's previous window, by a multiplier you set.
A condition can watch **all activity**, a specific **event** name, or a specific **page** path, over a
window you choose (168 hours by default) and against a minimum. You can scope a rule to **all accounts** or
**target accounts only**, limit it to specific projects, add up to five company filters (for example
industry equals SaaS), and set a cooldown so a busy account does not fire repeatedly.
Start from a template (Repeated Pricing Visits, Product Activation, Team Adoption, or Usage Growth) or
build a rule from scratch. Use **Preview Matches** to see which companies match right now before you turn
the rule on. Logspot evaluates enabled rules on a schedule, about every 15 minutes, and each organization
can have up to 20 rules.
A Custom Rule Matched signal behaves like any built-in one: it appears in the feed, can trigger an action,
and can reach your CRM through the HubSpot destination.
## Turning Signals On and Off
You can turn any built-in signal on or off for your organization from **Actions → Signals**. Pause the ones
you do not want, and enable them again later. Turning off **Target Account Visited** also turns off
**Return Visit**, since a return visit builds on a first visit.
## Noise Control
Every signal is deduplicated to at most one per account per day, and New ICP-Fit Company fires only once
per company for all time. A single account having a busy afternoon produces one signal, not thirty.
Each signal carries its evidence, so the feed shows which pages were visited or how far above normal the
volume was, rather than just a company name and a label. Signals also carry the account's acquisition
channel, so you can see which channels produce accounts that actually engage.
## Strength
Signals carry a strength of **Low**, **Medium**, or **High**, shown as an indicator in the feed. Use it
to triage when the feed is busy.
## Acting on a Signal
A signal can start an action. Add a signal trigger to a Send Notification action to route signals to
Slack or email, so they reach you where you work. Add the same trigger to an AI action such as Prospect
Research or Outreach Draft, and it runs for the signal's company and delivers the result, so the alert
becomes the start of the work rather than the end of it. AI runs spend credits.
A Send Notification action can also send target-account signals to your CRM. With the **HubSpot**
destination, the signal is written onto the matching HubSpot company, so your reps see the intent on the
record they already work in. See [HubSpot](/docs/integrations/hubspot).
See [Triggers and Cooldown](/docs/actions#triggers-and-cooldown).
## Related
* [Actions](/docs/actions)
* [Companies](/docs/companies)
* [Enrichment](/docs/enrichment)
# Companies
URL: /docs/companies
***
title: Companies
description: See which companies are using your product, how active they are, and what they are worth.
------------------------------------------------------------------------------------------------------
Logspot rolls individual people up into the companies they belong to, so you can ask account-level
questions instead of user-level ones. Go to **Analytics → Companies**.
## Where Companies Come From
There are two routes, and you can use both.
**Work-email domains.** When you [identify a user](/docs/identity) with a work email,
Logspot derives the company from the domain. Free and disposable mail providers are excluded, so a
personal address does not become a one-person company. That list is pragmatic rather than exhaustive,
so an unusual provider can occasionally slip through.
**The group API.** Call [`group()`](/docs/groups) to state the association yourself.
This is the better route when your product has real accounts, workspaces, or teams, because you know the
membership and Logspot does not have to infer it.
## The List
Each row is a company, with:
| Column | What it shows |
| ----------- | ---------------------------------------------------------------------------------- |
| Company | The company name |
| Domain | The domain it was resolved from |
| Users | How many identified people belong to it |
| Events | How much activity it has generated |
| Channel | The [acquisition channel](/docs/acquisition-channels) that first brought it to you |
| Revenue | Revenue attributed to it |
| Last Active | When someone from it was last seen |
Click a column header to sort by that metric. Open a row for the company detail view.
**Channel** is worth calling out, because it answers a question most analytics cannot: not just which
channels bring traffic, but which channels bring *accounts*. A channel with modest visit numbers that
delivers your best accounts is doing better work than its traffic count suggests.
## Plan Limits
Each plan tracks up to a set number of companies. When you reach it, the page shows a **Company Limit
Reached** notice and stops adding new ones. Existing companies keep updating. Upgrade from
**Settings → Billing** to raise the limit.
## Related
* [Groups and Companies](/docs/groups)
* [Identifying Users](/docs/identity)
* [Acquisition Channels](/docs/acquisition-channels)
# Groups and Companies
URL: /docs/groups
***
title: Groups and Companies
description: Roll users up into accounts — associate people with companies (or any group type), then analyze usage, members, and revenue per account in the Companies dashboard.
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
For B2B products, the unit that matters is often the **account**, not the
individual. Logspot lets you group users into **companies** (or any group type)
so you can answer "which accounts are most active?", "who are the people inside
Acme?", and "what's revenue by company?".
> Groups build on identity. Read [Identify Users and Profiles](/docs/identity)
> first — a group associates a *person* (or an anonymous visitor, promoted on
> identify) with an account.
## Associate a User with a Company
There are two ways to tie a user to a group.
### 1. The Group API (Recommended for Traits)
Send a group call from your backend to create/update a company and attach a
member. Use it when you want to set company **traits** (name, plan, domain, …):
```bash
curl -X POST https://api.logspot.io/v1/group \
-H "Authorization: Bearer sk_YOUR_API_TOKEN" \
-H "Content-Type: application/json" \
-d '{
"group_id": "acme.com",
"type": "company",
"user_id": "user_123",
"traits": { "name": "Acme, Inc.", "plan": "enterprise" }
}'
```
* **`group_id`** — a stable key for the account (a domain like `acme.com` is a
common choice).
* **`type`** — the group type; defaults to `company`.
* **`user_id`** (or **`anonymous_id`**) — the member to attach. If the visitor
isn't identified yet, the membership attaches to their anonymous ID and is
promoted to the person when they `identify()`.
* **`traits`** — properties on the account (a `name` shows in the dashboard).
See [API Authentication](/docs/api-authentication) for keys.
### 2. Inline on a Track Event
Any `track` call can carry `groupId` and `groupType` to associate that event (and
its user) with an account in the same call, from the browser SDK or your backend:
```js
Logspot.track({
event: 'Project Created',
userId: 'user_123',
groupId: 'acme.com',
groupType: 'company',
});
```
Posting directly to the raw [Track API](/docs/api-reference/events/trackEvent) uses
the snake\_case `group_id` / `group_type` fields with your API token.
> The [browser](/docs/sdk/js) and [Node](/docs/sdk/node) SDKs also expose a
> `group()` helper, e.g. `Logspot.group('acme.com', { plan: 'pro' })`, which
> creates or updates a membership without emitting an event.
## Group Types
`company` is the default and the right choice for most B2B accounts. You can
define **additional group types** (e.g. `workspace`, `team`) under
**Settings → Groups**, then pass that key as `type` / `group_type`. The
[Playground](https://app.logspot.io) group form lets you pick from your
configured types.
## The Companies Dashboard
Once associations are flowing, the **Companies** section gives you per-account
analytics:
* **Companies list** — every account, sortable by users, events, last active, or
revenue.
* **Company detail** — headline tiles (users, events, members, revenue, last
active), **revenue over time**, a **Members** table (the identified people in
the account, with role and last seen), **Top users** (most active people by
event count, linked to their profiles), and an **Activity** feed.
## Reporting on Other Group Types
Group types beyond `company` — such as a `workspace` or `team` you define under
**Settings → Groups** — get their own reporting view, separate from Companies.
Once memberships are flowing for a group type, open its report from the
**Groups** section to see the same account-style analytics for that unit: a
sortable list of groups, per-group metrics, and the most active members. It's the
Companies pattern applied to whatever unit matters for your product, so a
workspace- or team-based product can analyze usage by that unit without forcing
everything into "company."
# Identify Users and Profiles
URL: /docs/identity
***
title: Identify Users and Profiles
description: Turn anonymous visitors into known people — call identify(), stitch activity across devices, and explore per-person profiles, identities, and merge conflicts.
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------
Logspot links anonymous browsing to the real people behind it. Once you tell
Logspot who someone is, every event — before and after they signed in, on every
device — rolls up into one **profile**. This page covers how to identify users
and what you can do with the resulting identities.
> New to the model? Read [How Tracking and Identity Works](/docs/how-it-works)
> first for the anonymous-ID / user-ID / session mental model. This page is the
> practical "how to use it" guide.
## Identify a User
When a visitor tells you who they are (sign up, log in), call `identify()` with
your stable user ID and any traits:
```js
await Logspot.identify('user_123', {
email: 'user@example.com',
plan: 'pro',
name: 'Jane Doe',
});
```
That's it. From then on, every `track()` carries the same `user_id`, and Logspot
stamps the person's canonical identity onto their events at ingest. Activity from
*before* they identified (still anonymous) stitches to the same profile via the
anonymous ID.
You can also identify [server-side](/docs/sdk/node) — handy when the user ID
lives in your backend.
### Use a Stable ID
`user_id` is your system's stable identifier for the person — a database ID, or
an email if that's what you key on. It's matched **verbatim**, so send the same
value every time. Call [`reset()`](#log-out-with-reset) on logout so the next
visitor on a shared device starts fresh.
## Email & Other Traits
Traits describe the person (`plan`, `name`, `company`, anything). Two notes on
**email** specifically:
* **Email is searchable but not a merge key.** Whenever an `identify` carries an
email — explicit `email` trait, or an email-shaped `user_id` — Logspot attaches
a normalized (lower-cased) **email alias** to the identity. You can then search
for that person by email, and it stays unique within your organization.
* **Resolution happens on `user_id` and `anonymous_id` only.** Email is a
property, not a stitch trigger — so two different people who happen to share an
email are never silently merged.
## The Person Profile
Open any user to see their **profile** — a single timeline of who they are and
what they've done:
* **Headline stats** — events, pageviews, sessions, avg events/session, avg
session duration, bounce, active days, and revenue, for the selected range.
* **Profile card** — primary email, traits, first/last seen, and their company.
* **Location & device**, **activity calendar**, **trend charts**, **top
pages/referrers**, and a **sessions list**.
It's the same view for a customer in your User list and for an admin opening an
identity from Settings — only the scope differs.
## Find & Manage Identities
Go to **Settings → Identities** to work with the canonical identities behind your
data.
* **Identities** — search by any alias (`user_id`, `email`, `anonymous_id`)
within your organization, then open one for detail.
* **Identity detail** — inspect a person's **aliases**, current **traits**, and
recent **org-wide events** (across all your projects). You can **attach an
alias** (e.g. add an email), mark one as the primary email, or **unlink** the
identity (removes the canonical record; raw events keep their original IDs).
## Merges & Conflicts
Cross-device stitching is automatic, but occasionally an `identify` ties together
two people who had *already* become separate identities (e.g. a shared device).
Logspot never auto-merges these — it records a **conflict** and leaves the call
successful, so a high-volume mistake can't quietly fuse two customers.
Review them under **Settings → Identities → Conflicts**:
* **Merge** — fold the two identities into one (use when it really is the same
person).
* **Leave separate** — mark triaged without merging (use when they're genuinely
two people).
Toggle **Open / Resolved** to see history. A conflict clears only when you
explicitly triage it.
## Control How Identity Is Established
Per project, under **Project Settings → Identity**, two settings govern behavior:
**Identity Resolution** — how much a plain `track` event may establish identity:
| Mode | What a `track` event does | `identify()` |
| ------------------------------ | ------------------------------------------------------------------------------- | --------------------------------------------- |
| **Track & Identify** (default) | resolves, stamps, creates identities, and links an *unclaimed* alias on a match | full |
| **Identify** | resolves + stamps only — never creates or links | establishes identity |
| **Secure Identify** | resolves + stamps only | **must be cryptographically verified** (JWKS) |
**Secure Identify** is for when you need end-to-end proof a `user_id` claim came
from *your* backend. Forward a signed token:
```js
await Logspot.identify(
'user_123',
{ email: 'user@example.com' },
{ identityVerification: { token: jwtFromYourBackend } },
);
```
Then set the issuer, audience, JWKS URL, and allowed algorithms in Project
Settings.
**Participation** — `organization` (default; the project shares the org-wide
identity graph) or `project-only` (resolution is constrained to aliases that
originated in this project). Use project-only to isolate a project's identities
from the rest of your org.
## Log Out with `reset()`
```js
Logspot.reset();
```
`reset()` clears the identified user and registered properties and rotates the
anonymous ID locally (no network call). Call it on logout so a shared browser
doesn't attribute the next person's activity to the previous user.
## Privacy
Identity is built only from the IDs you provide plus a first-party anonymous
cookie — **no fingerprinting, no third-party cookies**. Identification is
consent-aware: events denied analytics consent are never counted, and a
data-subject erasure request removes a person's identity and events.
# Sessions
URL: /docs/sessions
***
title: Sessions
description: How Logspot groups a person's activity into sessions — server-side, deterministic, and without an extra session cookie.
------------------------------------------------------------------------------------------------------------------------------------
A **session** is a burst of activity by one person. Logspot derives sessions
**server-side** from the events you already send — there's no separate session
cookie or client-side timer to manage.
## How a Session Is Defined
Events from the same person (their [anonymous ID, or user ID once identified](/docs/how-it-works))
are grouped into a session using a **30-minute inactivity window**: a gap of
more than 30 minutes starts a new session. A short 5-minute grace at window
boundaries keeps continuous browsing from being split mid-flow.
Because the session ID is a **deterministic function** of the person + the time
bucket, the same activity always produces the same session — which means
sessions can be re-computed for historical data with no drift, and there's no
client state to tamper with.
## Where You'll See Sessions
* **Per person** — each [profile](/docs/identity#the-person-profile)
has a **Sessions** list, plus session counts and average session duration in
the headline stats.
* **Analytics** — sessions, average session duration, and bounce rate roll up
across your project.
## Pageviews & Bounce
A session with a single pageview and no further interaction counts as a
**bounce**. Average session duration measures the time between the first and
last event in a session.
## Privacy
Sessions add **no extra client-side storage** — they're computed from event
timestamps and the first-party anonymous ID you already have. Nothing about
sessions is stored in the visitor's browser.
# Visitor Identification
URL: /docs/visitor-identification
***
title: Visitor Identification
description: Resolve the company behind an anonymous visit, within a consent and region policy you control.
-----------------------------------------------------------------------------------------------------------
Most people who visit your site never fill in a form. Visitor identification resolves the company behind
those anonymous sessions from the network the visit came from, so an unattributed visit becomes an
account you can recognise.
## What You Get
A resolved visit stamps the company onto the session, which means anonymous traffic starts appearing in
[Companies](/docs/companies), feeds [Signals](/docs/signals), and counts
toward the company view of your funnels and reports.
Resolution is not universal. Visits from home internet providers and from hosting or VPN networks
aren't resolved, because those networks don't belong to a company, so some of your traffic will stay
anonymous.
## Turning It On
Once Logspot has enabled visitor identification for your organization, choose where it runs in
**Actions → Enrichment → Identify Anonymous Companies**: pick the projects whose anonymous visits
should be resolved. It is off for every project until you pick one.
## Consent and Regions
A visitor who has given explicit analytics consent, recorded by your consent banner, the API, or a stored
choice, is resolved wherever they are. The permissive "Not Required" default does not count as explicit
consent.
Without explicit consent, a **region policy** decides by the visitor's location: some regions resolve,
and others are skipped entirely. The default policy is **US only**: visitors in the United States
resolve, and everywhere else requires consent first. Logspot sets the region policy for your
organization; [contact us](/contact) to tighten or widen it.
Two design details worth knowing. The consent and region check runs before any cached result is
consulted, so a policy change takes effect immediately rather than after a cache expires, and a
non-consenting visitor is never resolved just because someone on the same network was resolved earlier.
And separately from all of this, whether you may use a resolved company for outbound purposes is decided
at the point you act on it, not at the point it is resolved.
## What It Costs
Each company is charged at most once per calendar month: the first time it is identified that month.
Later visits from the same company that month are free, whichever network they come from, and a lookup
that finds no company is never charged. Both meters are checked before the lookup runs, so a shortfall
skips the lookup rather than running it and billing you later. Topping up takes effect on the next event.
Results are kept for 30 days, including misses, so repeat visits from the same network don't trigger a
new lookup.
See [Actions and Data Credits](/docs/actions-data-credits).
## Related
* [Companies](/docs/companies)
* [Signals and Target Accounts](/docs/signals)
* [Consent Settings](/docs/consent-settings)
# Consent Settings
URL: /docs/consent-settings
***
title: Consent Settings
description: Set your organization's consent posture, connect a consent source, and decide what happens to events from visitors who decline.
--------------------------------------------------------------------------------------------------------------------------------------------
[Consent Management](/docs/consent) covers how a consent signal reaches Logspot from
your code or your CMP. This page covers the settings that decide what Logspot does with that signal.
Everything here lives under **Settings → Privacy**, which has four tabs: **User Consent**, **Consent
Sources**, **Server Events**, and **Data Requests**.
## Consent Behavior
**Settings → Privacy → User Consent** sets the **Default Behavior** for your organization. This is the
state Logspot assumes before any consent source has said otherwise.
| Option | What it means |
| ------------------- | -------------------------------------------------------------------------------------------------------------------------------- |
| Not Required | Standalone analytics. Analytics, Functional, and Marketing (Advertising) are all allowed unless a consent source restricts them. |
| Implied | All categories are granted until a visitor or your CMP denies them. |
| Express | Strict. Every category is denied until explicitly granted. |
| Custom Per Category | Set each category individually. |
Under **Custom Per Category**, each of the three categories takes either **Implied (Allowed by
Default)** or **Express (Denied Until Granted)**.
A project can depart from the organization default. Open **Project Settings → Consent** and use
**Override for This Project**.
## Analytics-Denied Events
When a visitor declines analytics, you choose what happens to their events:
**Discard the Event** drops them. Nothing is stored.
**Store Anonymized** keeps the event for aggregate counts but strips every identifier, including user,
anonymous, identity, company, and session. Metadata is dropped and location is truncated to country.
Choose this when you still need traffic totals from visitors you cannot identify.
## Server-Side Events
**Settings → Privacy → Server Events** decides how server-side events (sent with an API token or the
legacy secret key) interact with the analytics-denied rule. Client-side events from the browser SDK, sent
with the public key, are always gated, whatever you pick here.
**Exempt Revenue** is the recommended setting. A payment sent from your server is recorded under a
transactional basis and bypasses the analytics-denied rule, while other server-side events stay gated.
The denied stamp still blocks marketing and sale or share destinations downstream.
**Exempt All Server-Side** lets every server-side event bypass the rule. Use it when all your server-side
data is first-party and trusted.
**Gate Everything** puts server-side events through the same gate as client-side events. This is the
strictest option.
## Consent Sources and Priority
**Settings → Privacy → Consent Sources** is where you connect the systems that can tell Logspot about a
visitor's choices. More than one can be active, so Logspot ranks them.
The ladder, highest authority first:
1. The Logspot Consent API, meaning an explicit `setConsent()` call or a request to the consent endpoint
2. Concord
3. Third-party CMPs: OneTrust, Usercentrics, and Cookiebot
4. Google Consent Mode
5. The organization default
A source can overwrite a record written by anything below it, never by anything above it. The three
third-party CMPs share one rank, so among those the most recent write wins.
Google Consent Mode sits deliberately low. Logspot reads it but never writes to it, and a Consent Mode
state can be a site-configured default rather than a choice a person made. The reader cannot tell those
apart, so anything above it takes precedence.
## Browser Privacy Signals
Global Privacy Control and similar browser signals are always recorded. Whether they override a category
outcome depends on where that outcome came from.
If a real consent management platform produced the record, meaning the Consent API, Concord, OneTrust,
Usercentrics, or Cookiebot, its outcome stands and the signal is recorded alongside it. The reasoning is
that a person answered a question, and that answer is better evidence than a browser-level default.
If the record came from Google Consent Mode or from your organization default, a Global Privacy Control
signal does override it. Neither of those represents a human answering a question about your site, so a
visitor's explicit signal wins.
## Per-Person Consent History
Open **Settings → Identities** and select a person to see their current state for Analytics, Functional,
and Marketing (Advertising), along with the history of changes. Each event carries the source that
produced its consent state, so you can trace why a given event was treated the way it was.
## Related
* [Consent Management](/docs/consent)
* [Privacy Requests](/docs/privacy-requests)
* [Do Not Track](/docs/dnt)
# Consent Management
URL: /docs/consent
***
title: Consent Management
description: Tell Logspot what each event is allowed to be used for, from your CMP or a single API call.
--------------------------------------------------------------------------------------------------------
Logspot is consent-native: every event is stamped, at the moment it happens, with the permissions that applied to it. That stamp travels with the event for its whole life, so downstream reports, audiences, exports, and automated Actions all know what a given event is allowed to be used for.
Logspot is **not** a consent management platform (CMP). It *consumes* consent — from your existing CMP, from browser privacy signals, or from a single API call — and enforces it. If you already run a CMP, Logspot trusts its decisions; you don't configure consent rules in two places.
## Quick Start
If you manage consent yourself, tell Logspot the current state with `setConsent`:
```javascript
Logspot.setConsent({
analytics: true,
functional: true,
marketing: false,
doNotSellShare: true,
});
```
All fields are optional — send only the categories you've decided. Call it again whenever the user's choice changes; Logspot records the change and stamps subsequent events accordingly.
## Connect Your CMP Instead
If you use a CMP, point Logspot at it and skip the manual calls. Logspot reads the CMP's decisions directly:
```javascript
Logspot.init({
publicKey: 'YOUR_PUBLIC_KEY',
consentSources: ['concord'],
});
```
Supported sources: `concord` (the preferred integration), `onetrust`, `usercentrics`, `cookiebot`, and `gcm` (a read-only Google Consent Mode reader for sites already running Consent Mode). List more than one if you need to.
With the CDN snippet, use the `data-consent-source` attribute (comma-separated):
```html
```
When several sources are present, the most authoritative one wins, in this order: an explicit `setConsent` call, then Concord, then a third-party CMP (OneTrust / Usercentrics / Cookiebot), then the Google Consent Mode reader, then your organization's defaults. Logspot never re-interprets a CMP's decision — the CMP is the source of truth.
## Categories
Logspot uses three consent categories:
* **Analytics** — measuring product and site usage.
* **Functional** — features that remember the user (preferences, session continuity).
* **Marketing (Advertising)** — audience building, retargeting, ad measurement, and ad personalization.
These map to the standard categories your CMP already exposes, so no translation is needed.
## Default Behavior
If you never send consent, an organization-level setting decides the default. Set it under **Settings → Privacy → User Consent**:
* **Not required** (default) — analytics, functional, and marketing are all allowed. Best for standalone analytics where you don't gate on consent.
* **Implied** — all categories are allowed until the user declines.
* **Express** — all categories are denied until the user grants them.
* **Custom** — choose the default per category.
The same screen controls what happens to an event when analytics is *not* allowed: **drop** it at ingestion (the default) or **anonymize** it (store it with all identifiers removed so aggregate counts still work).
## Browser Privacy Signals
Logspot automatically detects **Global Privacy Control (GPC)** and **Global Privacy Platform (GPP)** signals and records them alongside the event, separate from the consent categories. When no CMP is connected, a GPC signal sets Do Not Sell/Share and turns marketing off. When a CMP *is* connected, the signal is recorded but the CMP's decision still stands.
## What the Stamp Unlocks
Because every event carries its permissions, you can:
* **Segment by consent** — built-in filters for Analytics Allowed, Functional Allowed, Marketing (Advertising) Allowed, Do Not Sell Enabled, GPC Detected, and Advertising Eligible.
* **Gate Actions and exports** — an Action that needs marketing consent won't run for events that don't carry it. See [Actions](/docs/actions).
* **Audit with confidence** — each identity keeps a full consent history (who, what, when, and which source decided), for compliance reviews and investigations.
## Related
* [Identifying Users](/docs/identity)
* [Actions](/docs/actions)
* [Do Not Track](/docs/dnt)
# Privacy Requests
URL: /docs/privacy-requests
***
title: Privacy Requests
description: Export or erase everything Logspot holds about a person (data subject requests, DSAR/DSR), from the dashboard or the API.
--------------------------------------------------------------------------------------------------------------------------------------
When someone exercises their right of access or erasure, Logspot can find every record tied to them and
either package it up or delete it. These are privacy requests, also called data subject requests (DSAR for
access, DSR for erasure). Both request types work from the dashboard and from the API.
Logspot is the processor and you are the controller, so verifying that a requester is who they claim to
be is your responsibility. Logspot acts on the identifiers you supply.
## Create a Request from the Dashboard
Go to **Settings → Privacy → Privacy Requests**. The **New Privacy Request** form takes four inputs:
**Type** is either **Export (DSAR)** or **Delete (DSR)**.
**Regulation** is **GDPR** or **CCPA**. This is recorded with the request so your audit trail shows the
basis it was handled under.
**Window** appears for exports only, and is either **All History** or **Trailing 12 Months**. CCPA
access requests are commonly scoped to the preceding twelve months, so the shorter window is there when
you need it.
**Subject Ids** takes one or more `user_id` or `anonymous_id` values, separated by commas, spaces, or
new lines. You can resolve several identifiers belonging to the same person in a single request.
Submitting an export creates the request and produces a downloadable artifact when it finishes. The
artifact expires after a period, so download it rather than relying on the link later.
## Deleting a Subject
Deletion asks for confirmation first. Logspot runs a preflight that counts how many records match the
identifiers you gave, and the confirmation dialog, **Permanently Delete This Subject?**, shows that
count before you commit.
Deletion is irreversible and reaches every store Logspot keeps the subject's data in. There is no undo
and no recovery from backup, so check the matched count looks right before confirming.
## Track a Request
The **Request History** table on the same page lists recent requests for your organization with their
status. Every request records the identifiers it resolved and how many records it matched, so you can
evidence what was done after the fact.
## The API
The same operations are available over the API for teams routing requests from their own privacy tooling.
A privacy request spans your whole organization, so these endpoints take an **organization-scoped API
token** with the `privacy_requests:write` scope (and `privacy_requests:read` to list, poll, or download).
A project key cannot file them. See [API Authentication](/docs/api-authentication).
Create a deletion request:
```bash
curl https://api.logspot.io/v1/privacy-requests \
-H "Content-Type: application/json" \
-H "Authorization: Bearer sk_a1b2c3d4e5f6" \
-d '{"request_type": "deletion", "distinct_ids": ["user_42"], "regulation": "GDPR"}'
```
Create an export request with a twelve-month window:
```bash
curl https://api.logspot.io/v1/privacy-requests \
-H "Content-Type: application/json" \
-H "Authorization: Bearer sk_a1b2c3d4e5f6" \
-d '{"request_type": "export", "distinct_ids": ["user_42"], "regulation": "CCPA", "window": "trailing_12_months"}'
```
Both return `202` with the request wrapped in the standard success envelope:
```json
{ "status": "OK", "data": { "id": "...", "status": "pending" } }
```
List your organization's requests with `GET /v1/privacy-requests`, poll one with
`GET /v1/privacy-requests/{id}`, and fetch a finished export from
`GET /v1/privacy-requests/{id}/download`.
Deletion requests are rate limited more tightly than exports (5 per minute against 30), since they are
destructive.
## What a Request Covers
Requests resolve against a person: the `user_id` and `anonymous_id` values that identify a human being.
Company records are not in scope, because a company is not a person.
## Related
* [Consent Management](/docs/consent)
* [Identify Users and Profiles](/docs/identity)
* [Do Not Track](/docs/dnt)
# Connect Claude and AI Assistants (MCP)
URL: /docs/mcp
***
title: Connect Claude and AI Assistants (MCP)
description: Ask Claude, ChatGPT, Cursor, and other MCP-compatible AI tools about your Logspot analytics (events, users, funnels, journeys, retention, revenue, companies, groups, and profiles) over a secure connection you control, and optionally let them take actions on your behalf.
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
Logspot ships a hosted **MCP server** (Model Context Protocol) so you can connect
Claude, ChatGPT, Cursor, or any MCP-compatible AI assistant directly to your
analytics and just *ask* questions in plain language. No SQL, no dashboards, no
exporting CSVs.
> **MCP** is an open standard for connecting AI assistants to external tools and
> data. Logspot's server is **remote** (hosted by us) and **OAuth-secured**. By
> default the assistant can *read* your data. You can optionally grant a small set
> of write tools that let it act on your behalf: you choose on the consent
> screen, and it is off until you turn it on.
You can set all of this up in the app too, at **Integrations → AI & API Access →
AI Assistants (MCP)**, where each client below has its own tab.
## What You Can Ask
Once connected, ask Claude things like:
* "How many signups did we get last week, broken down by plan?"
* "What's the 30-day retention for users who completed onboarding?"
* "Show me the top companies by revenue this month."
* "What did `jane@acme.com` do before they upgraded?"
* "Which step of the checkout funnel drops off the most, and what path do people take instead?"
Claude calls the matching Logspot tool, scopes it to your organization, and
answers from live data.
## Connect Claude
**Claude and Claude Desktop.** In Claude, open **Settings → Connectors** (web or
desktop), choose **Add custom connector**, and enter the Logspot MCP URL:
```
https://api.logspot.io/mcp
```
Click **Connect** and complete the sign-in. Claude opens Logspot's secure login
(OAuth) in a new window. Approve access for the organization you want Claude to
read, then start a new chat and ask one of the questions above.
See Anthropic's [custom connectors guide](https://support.claude.com/en/articles/11175166-get-started-with-custom-connectors-using-remote-mcp)
for the exact menu locations in your Claude plan.
**Claude Code.** From your terminal:
```bash
claude mcp add --transport http logspot https://api.logspot.io/mcp
```
Then run `/mcp` in Claude Code and approve the browser sign-in.
## Connect ChatGPT
ChatGPT connects to a remote MCP server through **developer mode**. Turn on
developer mode in ChatGPT's settings, add a connector for the Logspot server URL,
and sign in when prompted:
```
https://api.logspot.io/mcp
```
Developer mode connectors are available on paid ChatGPT plans (Plus, Pro,
Business, Enterprise, and Education) on the web. See OpenAI's
[developer mode guide](https://developers.openai.com/api/docs/guides/developer-mode)
for the current steps and plan availability.
For OpenAI Codex:
```bash
codex mcp add logspot --url https://api.logspot.io/mcp
```
Then run `codex mcp login logspot` and approve the browser sign-in.
## Connect Cursor
Use Cursor's one-click install, then approve the Logspot sign-in. If you prefer to
edit config by hand, add the server to `~/.cursor/mcp.json` (or `.cursor/mcp.json`
in a single project):
```json
{
"mcpServers": {
"logspot": {
"url": "https://api.logspot.io/mcp"
}
}
}
```
## Connect Other Assistants
Any MCP client that supports remote servers over HTTP, such as VS Code, Windsurf,
and Gemini CLI, connects the same way. Add the server URL
```
https://api.logspot.io/mcp
```
in the client's MCP or connector settings, then complete the Logspot sign-in and
approve the scopes. Check your client's own MCP docs for where it lists servers.
## New to Logspot?
You can connect the MCP server before you finish signing up. Approving the
connection sends you to onboarding to create your organization on the Free plan,
then back to your assistant. You can build your first Company Profile there, and
the first build is free.
## What Claude Can Access
Each tool is **scoped to the organization you authorize**, with the same
permissions your own account has in the dashboard. The read tools cover:
| Area | Examples |
| --------------------------------- | ----------------------------------------------------------------------------------------------- |
| **Analytics** | event counts, daily/cumulative trends, unique users, property breakdowns and sums, search |
| **Funnels, journeys & retention** | multi-step conversion, path and journey analysis, cohort retention |
| **Revenue** | totals, time series, by attribution/property, top accounts, LTV cohorts |
| **Companies** | top companies, company metrics, revenue, and most-active users |
| **Groups** | reporting on non-company group types, such as workspaces or teams |
| **Actions** | the action catalog and your saved actions |
| **Profiles & sessions** | a person's activity, pages, referrers, device/geo, and sessions (looked up by email or user ID) |
| **Projects** | the organization's projects, so the assistant can pick the right one |
If you grant write access (see below), the assistant can also **create a target
account, update or build a company profile, and create or run an action**.
## Privacy & Security
* **OAuth, not API keys.** You authenticate through Logspot's normal login. No
long-lived secret is pasted into Claude. Access is limited to the scopes you
approve on the consent screen.
* **You choose the permissions.** The consent screen shows what the connector
will access, with a Customize option to review each one. Turn off anything you
do not want to share; tools that need it are not offered to the assistant on
that connection.
* **Read by default, write only if you turn it on.** The tools read your data
unless you enable the **"Make changes on your behalf"** option. That option
adds a small set of write tools (creating a target account, updating or building
a company profile, and creating or running an action), each left unchecked until
you choose it, and available only to owners and admins. Running an action can
spend Data Credits, exactly as it would from the dashboard.
* **Organization-scoped.** Claude only ever sees the organization you approved.
Any member can connect; the company, group, revenue, action, and profile tools
additionally require your account to be an owner or admin of that organization.
* **Revocable.** Remove the connector in Claude, or in Logspot go to
**Integrations → AI & API Access → AI Assistants (MCP) → Connected
Applications** and choose **Revoke Access**, at any time.
* **Consent-aware.** Profile and analytics tools respect the same consent gating
as the rest of Logspot, so denied-analytics events are never counted.
## Troubleshooting
* **"Couldn't connect" or sign-in loops.** Make sure pop-ups are allowed for
Claude, and that you're logged into the right Logspot organization.
* **"No data" answers.** Confirm the connected organization actually has events
in the time range you're asking about. Company, group, revenue, action, and
profile questions also need your account to be an owner or admin of that
organization.
* **Want the assistant to take actions?** Turn on **"Make changes on your
behalf"** when you connect (owner or admin only). It can then create target
accounts, update or build company profiles, and create or run actions; running
an action can spend Data Credits. For scripted or service automation, create an
[API token](/docs/api-authentication) and call the
[REST API](/docs/api-reference/events/trackEvent) or [SDKs](/docs/sdk/js).
## Related
* [Integrations](/docs/integrations)
* [API Authentication](/docs/api-authentication)
# Receiving Webhooks
URL: /docs/receiving-webhooks
***
title: Receiving Webhooks
description: Receive webhook deliveries from Logspot, verify they came from us, and handle retries correctly.
-------------------------------------------------------------------------------------------------------------
A webhook destination sends an HTTP request to your endpoint when an action fires. This page is for
whoever builds the receiving end.
To create one, add a [Send Notification](/docs/actions) action and choose a webhook
destination. For the opposite direction, sending events into Logspot, see
[Track an event](/docs/api-reference/events/trackEvent).
## What We Send
Every delivery is a `POST` with a JSON body and these headers:
| Header | Meaning |
| ----------------------------- | ------------------------------------------------------------------- |
| `x-logspot-event-type` | The event that fired the webhook |
| `x-logspot-delivery-id` | Unique id for this delivery, stable across retries |
| `x-logspot-signature` | Hex HMAC-SHA256 proving the request came from Logspot |
| `x-logspot-signature-version` | The signing scheme, `v1` or `legacy` |
| `x-logspot-timestamp` | Unix seconds when we signed, sent with `v1` only |
| `x-logspot-test` | `true` on a test sent with **Send Test**, absent on real deliveries |
| `Content-Type` | `application/json` |
The default body names the event and the project:
```json
{ "event": "Signup Completed", "projectId": "proj_123" }
```
A test sent with **Send Test** adds `"test": true` to this body. If you configure a custom payload,
that object is sent verbatim instead.
Custom headers you configure are sent too. They are merged before Logspot's signing headers, so a custom
header cannot override the security headers. It can override `Content-Type` or `x-logspot-event-type`.
## Your Signing Secret
Each webhook has its own secret, shown in the **Signing Secret** field when you set the webhook up.
Treat it like a password, because anyone holding it can forge deliveries.
Editing a webhook's URL, headers, or payload does not change its secret. To roll one, recreate the
webhook destination so a new secret is minted, then update your receiver. Deliveries sign with the new
secret immediately, so plan for a brief overlap.
## Verifying the Signature
Compute the HMAC yourself and compare it against `x-logspot-signature`.
For `v1`, which every new webhook uses, sign the string `"{timestamp}.{body}"`, where the timestamp is
the `x-logspot-timestamp` header and the body is the raw request bytes. For `legacy`, used by webhooks
carried over from the older trigger system, sign the raw body alone and expect no timestamp header.
The body must be the exact bytes you received. A re-serialized JSON object will not match.
Reject `v1` requests whose timestamp is too old. Five minutes is a sensible tolerance, and it is what
stops a captured request being replayed later. Always compare with a constant-time comparison.
```js
import crypto from 'node:crypto';
// `rawBody` must be the exact bytes received, e.g. via express.raw()
// or bodyParser's verify hook. A re-stringified object will NOT match.
export function verifyLogspotWebhook(headers, rawBody, secret) {
const signature = headers['x-logspot-signature'];
if (!signature) return false;
const version = headers['x-logspot-signature-version'];
const signedPayload =
version === 'v1' ? `${headers['x-logspot-timestamp']}.${rawBody}` : rawBody;
const expected = crypto
.createHmac('sha256', secret)
.update(signedPayload)
.digest('hex');
const a = Buffer.from(signature, 'hex');
const b = Buffer.from(expected, 'hex');
if (a.length !== b.length || !crypto.timingSafeEqual(a, b)) return false;
if (version === 'v1') {
const ageSeconds = Math.abs(
Date.now() / 1000 - Number(headers['x-logspot-timestamp']),
);
if (ageSeconds > 300) return false; // replay window: 5 minutes
}
return true;
}
```
## Delivery Behavior
Respond with a `2xx` quickly. Anything else counts as a failure, and we time out after five seconds.
Acknowledge first, then do slow work.
Failures are retried on a backoff of roughly one minute, five minutes, thirty minutes, two hours, and
eight hours. That is five retries across about ten and a half hours, after which the delivery is marked
failed in the Actions activity log. Configuration errors such as an unreachable or blocked URL are not
retried and fail immediately.
Deliveries are at-least-once. A retry can race a slow success, so duplicates are possible. Dedupe on
`x-logspot-delivery-id`, which stays the same across every attempt of the same delivery.
There is no ordering guarantee, so do not assume deliveries arrive in event order.
Targets must be publicly reachable. URLs resolving to private or internal networks are refused both when
the webhook is saved and when it would be delivered.
## Related
* [Actions](/docs/actions)
# Acquisition Channels
URL: /docs/acquisition-channels
***
title: Acquisition Channels
description: See which channel brought each visit, including traffic referred by AI assistants.
-----------------------------------------------------------------------------------------------
Logspot sorts every visit into one of seven acquisition channels so you can see where traffic comes
from without tagging every link yourself. Classification happens when you run a report, not when the
event arrives, so the channel breakdown covers your full history from the day you started tracking.
There is no backfill step and nothing to configure.
## The Seven Channels
| Channel | What lands here |
| -------------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| Paid Search | A search engine referral or source, with a paid `utm_medium` such as `cpc` or `ppc`. |
| Email | `utm_medium` or `utm_source` is an email token: `email`, `newsletter`, and variants. |
| AI Assistant | A referral or source matching a known assistant host, such as `chatgpt.com`, `claude.ai`, `perplexity.ai`, or `gemini.google.com`. |
| Organic Search | A search engine referral or source with no paid medium, or `utm_medium=organic`. |
| Social | A referral or source matching a social host, such as `linkedin.com`, `x.com`, `reddit.com`, or `news.ycombinator.com`. |
| Referral | Any other visit that arrived with a referrer or a `utm_source`. |
| Direct | No referrer and no `utm_source`. Someone typed the address, used a bookmark, or arrived from an app that strips referrers. |
## How a Visit Is Classified
Logspot reads three things: the referrer, `utm_source`, and `utm_medium`. It then walks the table above
from top to bottom and stops at the first channel that matches.
Order matters, and Paid Search deliberately sits above Organic Search. The organic rule is a superset of
the paid rule, so checking organic first would classify ad clicks as free traffic.
Two details worth knowing:
`utm_source` is matched as well as the referrer. Assistants often send no referrer at all, and some
stamp a source instead. ChatGPT, for example, sets `utm_source=chatgpt.com`. Matching both means a visit
is classified correctly whichever way it arrives.
Host matching is exact, or a true subdomain. `chat.openai.com` matches `openai.com`, but
`notchatgpt.com` and `chatgpt.com.example.org` do not. A lookalike domain cannot borrow another
channel's classification.
## Where Channels Appear
Add the **Channels** widget to any dashboard from the widget picker to see the breakdown for a date
range.
On **Analytics → Revenue**, switch the breakdown selector to **Channel** to see revenue by channel
rather than by source, medium, or campaign.
On **Analytics → Companies**, each company shows the channel that first brought it to your site.
## Tracking AI Assistant Traffic
AI Assistant is a first-class channel rather than a bucket inside Referral, because assistant traffic
behaves differently from a normal link click and is worth measuring on its own.
Detection depends on the assistant sending a referrer or a `utm_source`. Some assistants send neither,
and traffic from those lands in Direct instead. A low AI Assistant count is therefore a floor rather
than a precise figure. The hosts Logspot matches are drawn from published referrer observations where
those exist, and from product names where they do not, so the list grows as assistants change what they
send.
## Related
* [Campaign Tracking](/docs/campaigns)
* [Revenue Tracking and Attribution](/docs/revenue)
* [Sessions](/docs/sessions)
# Autocapture
URL: /docs/autocapture
***
title: Autocapture
description: Capture outbound clicks, downloads, form submissions, and media engagement without writing tracking code.
----------------------------------------------------------------------------------------------------------------------
Autocapture records common interactions without you writing a `track()` call for each one. The web SDK
does the instrumentation and you turn types on and off from the dashboard.
Autocaptured interactions are ordinary events with canonical names, so everything that applies to your
other events applies to them too: consent gating, attribution, filters, funnels, and queries.
## Turning It On
Autocapture is off for every project by default. Go to **Project Settings → Autocapture** and switch on
**Enable autocapture**, then choose the types you want.
Changes reach visitors without touching your installed snippet. The configuration rides along with the
normal tracking response, and the SDK applies it on the next page load, so a toggle you flip now takes
effect for returning visitors shortly after.
If no configuration is available for any reason, autocapture stays off. Pageview tracking is separate
and is never affected.
## What It Captures
Every type records metadata only. None of them record what a person types.
| Type | Events | What is recorded |
| ---------------- | ------------------------------------------------------------------- | -------------------------------------------------------------- |
| Outbound links | `Outbound Link` | The destination URL and the link text |
| File downloads | `File Downloaded` | The URL, file name, and extension |
| Form submissions | `Form Submitted` | The form's id, name, and action, never field values |
| Video and audio | `Media Played`, `Media Paused`, `Media Progress`, `Media Completed` | Media type, source, title, percent, duration, and current time |
File downloads are detected from a link's `download` attribute or from a list of file extensions you can
edit per project, covering the usual documents, archives, and media formats.
Video and audio instruments native `